<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jacobstrock.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jacobstrock.com/" rel="alternate" type="text/html" /><updated>2026-04-10T19:48:49+00:00</updated><id>https://jacobstrock.com/feed.xml</id><title type="html">Jacob P. Strock</title><subtitle>Turning big data into scientific and business insights</subtitle><author><name>Jacob P. Strock</name></author><entry><title type="html">Llm Rag Analyst</title><link href="https://jacobstrock.com/2025/01/30/LLM-RAG-Analyst.html" rel="alternate" type="text/html" title="Llm Rag Analyst" /><published>2025-01-30T00:00:00+00:00</published><updated>2025-01-30T00:00:00+00:00</updated><id>https://jacobstrock.com/2025/01/30/LLM-RAG-Analyst-</id><content type="html" xml:base="https://jacobstrock.com/2025/01/30/LLM-RAG-Analyst.html"><![CDATA[<h1 id="ai-covid--flu-analyst">AI COVID + Flu Analyst</h1>

<p><img src="/assets/images/Post_Images/LLMRAG/logo_banner.png" alt="Logo Banner" /></p>

<p>I built this as a test project to explore the forefront of LLM tools and opportunities in public health. The AI COVID + Flu Analyst app is a tool designed for today’s healthcare challenges. Developed using Streamlit, this app not only taps into millions of news sources and up-to-the-minute CDC data but also incorporates an LLM RAG (Retrieval-Augmented Generation) architecture, showcasing our commitment to advancing AI applications in meaningful ways. I built this project as a perfect platform to experiment with LLM RAG architectures, delve into LanChain operations, utilize the OpenAI API, and engage with Streamlit community cloud. Aimed at providing a robust monitoring dashboard, the app integrates several forecasting methods to track and analyze flu and COVID infections, setting a new standard in disease surveillance and response.</p>

<p>Check out the cloud hosted app here : <a href="https://llm-infection-analyst.streamlit.app/">Streamlit App</a></p>

<h2 id="features">Features</h2>

<h3 id="1-descriptive--predictive-infection-dashboard">1. Descriptive &amp; Predictive Infection Dashboard</h3>
<ul>
  <li><strong>Description</strong>: Displays the latest infection data in the US from the CDC, combined with Census geo-spatial data.</li>
  <li><strong>Visualization</strong>: Maps infections by total number and rate.</li>
  <li><strong>Forecasting</strong>: ARIMA models forecast infection numbers, offering insight into bulk numbers by state and region.</li>
</ul>

<h3 id="2-interactive-ai-news-analyst">2. Interactive AI News Analyst</h3>
<ul>
  <li><strong>Functionality</strong>: Uses an LLM RAG deployment to allow users to interactively query the latest news on COVID and hospitalizations in the US and globally.</li>
</ul>

<h3 id="3-forecasted-hospital-burden">3. Forecasted Hospital Burden</h3>
<ul>
  <li><strong>Prediction</strong>: Forecasts the impact on each state’s hospital systems by predicting infections, hospitalization rates, and hospital capacity.</li>
  <li><strong>Insights</strong>: Evaluates the burden of flu and COVID patients on hospital bed capacity and issues warnings for potential capacity concerns.</li>
</ul>

<h2 id="quick-start-guide">Quick Start Guide</h2>

<p>Follow these steps to set up and run the app on your local machine.</p>

<h3 id="prerequisites">Prerequisites</h3>
<ol>
  <li>Install <a href="https://git-scm.com/book/en/v2/Getting-Started-Installing-Git">Git</a>.</li>
  <li>Create an account on the <a href="https://platform.openai.com/docs/overview">OpenAI Developer Platform</a>.</li>
  <li>Create a free account with <a href="https://newsapi.ai/">News API</a>.</li>
</ol>

<h3 id="setup">Setup</h3>
<ol>
  <li><strong>Clone the Repository</strong>:
    <div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code> git clone https://github.com/yourusername/yourproject.git
 <span class="nb">cd </span>yourproject
</code></pre></div>    </div>
  </li>
  <li><strong>Update the API Keys</strong>:
    <ul>
      <li>Add your OpenAI API Key to <code class="language-plaintext highlighter-rouge">oai_template.yaml</code> and rename the file to <code class="language-plaintext highlighter-rouge">oai.yaml</code>.</li>
      <li>Add your News API Key to <code class="language-plaintext highlighter-rouge">newsapi_template.yaml</code> and rename the file to <code class="language-plaintext highlighter-rouge">newsapi.yaml</code>.</li>
    </ul>
  </li>
  <li><strong>Setup the Python Virtual Environment</strong>:
    <div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code> venv/Scripts/Activate
</code></pre></div>    </div>
  </li>
  <li><strong>Run the Streamlit App</strong>:
    <div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code> streamlit run ./src/streamlit/app.py
</code></pre></div>    </div>
  </li>
</ol>

<h3 id="access-the-app">Access the App</h3>
<p>Once the server is running, open your browser and navigate to <a href="http://localhost:8182">http://localhost:8182</a>.</p>

<hr />
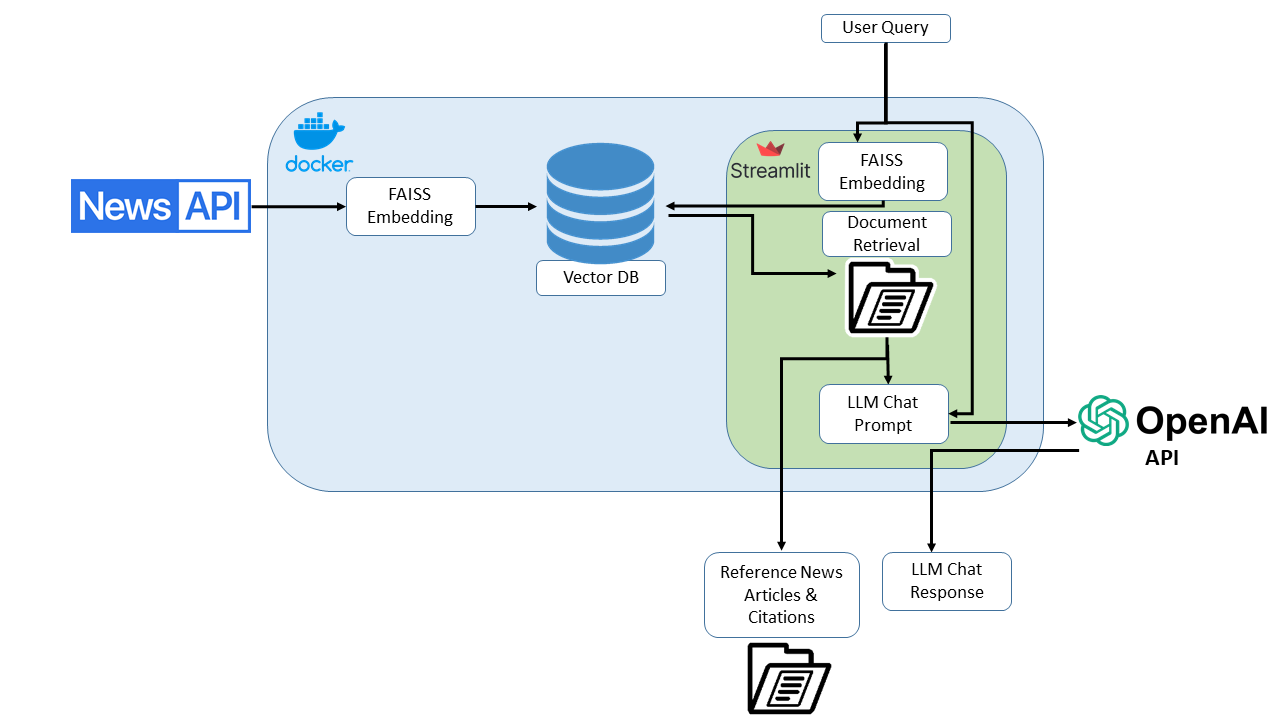
<p>This section outlines the architecture and functionality of the implemented Retrieval-Augmented Generation (RAG) model, which integrates news data from NewsAPI, user query handling through Streamlit, and response generation using OpenAI’s API.</p>

<p>Workflow Description</p>
<ol>
  <li><strong>Data Ingestion and Processing</strong>
     Source: News articles are fetched from NewsAPI.
     Embedding: Articles are converted into vector representations using FAISS (Facebook AI Similarity Search) embeddings, which capture the semantic content of the articles for effective retrieval.</li>
  <li><strong>Vector Database Storage</strong>
     Storage: The embeddings are stored in a Vector Database optimized for fast and accurate similarity searches.</li>
  <li><strong>User Query Interface</strong>
     Interface: Users input queries via a Streamlit-based interface, designed for simplicity and ease of use.</li>
  <li><strong>Document Retrieval</strong>
     Retrieval: Upon receiving a user query, the system retrieves the most relevant documents from the Vector Database using the semantic similarity of their embeddings to the query.</li>
  <li><strong>Integration with OpenAI Models</strong>
     Contextualization: The retrieved documents provide context to the OpenAI model, enhancing its ability to generate relevant and informed responses.</li>
  <li><strong>Response Generation</strong>
     Output: The system generates responses that are augmented with information directly cited from the retrieved documents, ensuring that responses are both relevant and grounded in sourced data.
     System Benefits
     Accuracy: Combines the computational efficiency of FAISS embeddings with the linguistic prowess of OpenAI models.
     Relevance: Ensures responses are contextually relevant by using document retrieval as a basis for response generation.
     Efficiency: Provides quick and reliable access to information through an optimized vector database.</li>
</ol>

<p><img src="/assets/images/Post_Images/LLMRAG/LLM_diagram.png" alt="LLM RAG Diagram" /></p>

<hr />

<p>This section provides an overview of the data engineering techniques employed in the system to fetch and process real-time news stories from NewsAPI and epidemiological data from the CDC via the Delphi Epidata API.</p>

<h3 id="news-data-retrieval">News Data Retrieval</h3>
<p>The system dynamically retrieves current news stories from NewsAPI, which are then processed to serve as the foundation for generating insights:</p>

<ul>
  <li><strong>API Integration :</strong> News stories are fetched in real-time using NewsAPI, ensuring the content is current and relevant.</li>
  <li><strong>Data Handling :</strong> Stories are parsed and necessary attributes like headlines, content, and publication dates are extracted and stored for further processing.</li>
</ul>

<h3 id="covid-data-acquisition">COVID Data Acquisition</h3>
<p>We obtain real-time epidemiological data directly from the CDC through the Delphi Epidata API. This process is detailed in the following steps:</p>

<ul>
  <li><strong>API Usage :</strong> The system makes requests to the Delphi Epidata API to fetch the latest available data on flu and COVID-like illness surveillance.</li>
  <li><strong>Date Range Handling :</strong> Data for specific epidemiological weeks (epiweeks) is requested, with the system calculating the range based on the current date to ensure the most recent data is retrieved.</li>
  <li><strong>Data Transformation :</strong> Retrieved data is transformed into a structured format, making it suitable for analysis and integration into the system’s data pipeline.</li>
</ul>

<h3 id="data-storage-and-access">Data Storage and Access</h3>
<p>Data fetched from both NewsAPI and the CDC is stored locally to facilitate quick access and processing:</p>

<ul>
  <li><strong>Temporary Storage :</strong> News articles and COVID data are initially stored in a temporary directory, which is periodically cleaned to ensure data freshness and relevance.</li>
  <li><strong>Reference Data Management :</strong> Static reference data, such as state population statistics, is stored separately and utilized to enrich the COVID data with demographic insights.</li>
</ul>

<h3 id="on-demand-data-refresh">On-Demand Data Refresh</h3>
<p>To manage computational resources efficiently and avoid unnecessary data fetches, the system employs an on-demand data refresh strategy:</p>

<ul>
  <li><strong>Streamlit Interface :</strong> Users can trigger data updates directly from the Streamlit interface via a ‘Refresh Data’ button. This ensures that the dashboard displays the most current information without the need for continuous background processing.</li>
  <li><strong>Session State Management :</strong> Upon refreshing, the new data is loaded and saved to Streamlit’s session state. This approach ensures that the updated state is retained across app refreshes and during the user session, enhancing the user experience by providing continuity and speed in data interaction.</li>
</ul>

<h3 id="automated-data-processing">Automated Data Processing</h3>
<p>Once new data is fetched, it is processed automatically to update the system’s insights:</p>

<ul>
  <li><strong>Data Preprocessing :</strong> New data goes through a cleaning and preprocessing pipeline to match the system’s requirements for analysis.</li>
  <li><strong>Information Retrieval Setup :</strong> For the RAG system, news data is embedded using machine learning models and stored in a vector database for quick retrieval based on semantic similarity to user queries.</li>
</ul>

<h3 id="conclusion">Conclusion</h3>
<p>Our data engineering practices are designed to ensure that the system remains responsive and current, providing users with reliable and up-to-date information. The integration of on-demand refresh capabilities with robust data processing pipelines allows for efficient resource usage while maintaining high data quality and system performance.</p>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[AI COVID + Flu Analyst]]></summary></entry><entry><title type="html">Building a fab data platform</title><link href="https://jacobstrock.com/2024/01/01/Building-A-Fab-Data-Platform.html" rel="alternate" type="text/html" title="Building a fab data platform" /><published>2024-01-01T00:00:00+00:00</published><updated>2024-01-01T00:00:00+00:00</updated><id>https://jacobstrock.com/2024/01/01/Building%20A%20Fab%20Data%20Platform</id><content type="html" xml:base="https://jacobstrock.com/2024/01/01/Building-A-Fab-Data-Platform.html"><![CDATA[<p><img src="/assets/images/Fabscape_MarchPromo.jfif" alt="Fabscape Demo" /></p>

<h1 id="demystifying-data-in-semiconductor-manufacturing-with-fabscape">Demystifying Data in Semiconductor Manufacturing with Fabscape</h1>

<p>In the intricate and ever-evolving world of semiconductor manufacturing, the ability 
to seamlessly collect, analyze, and visualize data is more crucial than ever. Fabscape, 
an open platform designed for the semiconductor industry, stands out by offering these 
capabilities in a customizable and collaborative environment. My experience with 
Fabscape, shared during a live demo with Semiconductor Digest in March 2023, 
highlights the platform’s utility and my role in enhancing its data capabilities.</p>

<h2 id="the-genesis-of-our-fabscape-demo">The Genesis of Our Fabscape Demo</h2>
<p>Alongside Yuji Minegishi from Gigaphoton, I demonstrated how semiconductor developers 
could transform a blank slate into a dynamic data visualization tool using Fabscape. 
This platform isn’t just another software suite; it’s a robust foundation for 
innovation in data management within the semiconductor sector.</p>

<h2 id="building-blocks-of-fabscape">Building Blocks of Fabscape</h2>
<p>Fabscape is built on a modular structure that supports extensive customization
 through plugins and drivers. These components are essential for tailoring the 
 platform to meet the specific needs of device manufacturers and equipment vendors:</p>

<ul>
  <li><strong>Plugins:</strong> These add functionalities to Fabscape, allowing for specialized data 
visualization. Without plugins, Fabscape would be merely an empty shell.</li>
  <li><strong>Drivers:</strong> These are crucial for data acquisition, tasked with collecting data 
directly from equipment and making it accessible to Fabscape’s backend. Like plugins, 
drivers are deployed as Docker containers, simplifying development and deployment and
making individual services (including ML services) modular.</li>
</ul>

<h2 id="my-role-in-the-digital-transformation-department">My Role in the Digital Transformation Department</h2>
<p>As a member of the Digital Transformation Department at Gigaphoton, 
I contributed to enhancing the data capabilities of Fabscape, particularly in the realm of 
machine learning. I developed several key plugins for Gigaphoton equipment that enabled 
advanced ML model functionalities, aligning with the strict security, 
hardware, and communication standards of the semiconductor manufacturing environment. 
My focus was on designing plugins that facilitate the ingestion, storage, and processing 
of data, as well as serving sophisticated machine learning models. This included implementing 
architectures that support the seamless integration of these models into Fabscape, and 
setting up systems to monitor their performance and facilitate ongoing development.</p>

<h2 id="from-data-collection-to-predictive-analytics">From Data Collection to Predictive Analytics</h2>
<p>During the demo, I created a driver to collect data—not from semiconductor equipment but 
from a public API providing COVID statistics. This example illustrated how Fabscape could 
be adapted for various data sources. We chose gRPC for the protocol to fetch data due to 
its high performance and efficiency in low-latency, high-throughput scenarios, which are 
crucial in semiconductor manufacturing environments. Additionally, gRPC’s strong type-safety, 
straightforward IDL (Interface Definition Language), and support for multiple programming 
environments make it an ideal choice for our scalable and interoperable system. I then 
integrated a user interface that leveraged reusable code components to display this data effectively.</p>

<p>Further extending Fabscape’s capabilities, I showcased how to integrate AI and machine 
learning for predictive analytics. Using a custom Jupyter Notebook plugin developed for
 Fabscape, we were able to pull equipment parameter data, apply machine learning models, 
 and perform predictive analytics to forecast equipment behavior.</p>

<h2 id="why-fabscape">Why Fabscape?</h2>
<p>Fabscape’s architecture promotes a collaborative approach, crucial for tackling complex
 challenges in semiconductor manufacturing. Its ability to be customized with proprietary
  and secure data solutions allows organizations to maintain data privacy while benefiting
   from shared innovations.</p>

<h2 id="engage-with-fabscape">Engage with Fabscape</h2>
<p>For those interested in exploring the potential of Fabscape, the platform offers a free 
Toolkit for developers. For more tailored solutions, Gigaphoton’s Advisory Program 
provides an opportunity to work directly with experts like myself to refine your data 
strategy and enhance your manufacturing processes.</p>

<h2 id="conclusion">Conclusion</h2>
<p>The full capabilities of Fabscape were on display during the Semiconductor Digest webinar, 
which is available on demand. This event was not only a demonstration of technology but 
also a testament to the collaborative and innovative spirit that drives the semiconductor
 industry forward, and my role as a data scientist and engineer in shaping this future.</p>

<p>I invite you to watch the full recording to appreciate the depth of the solutions provided 
and to understand how Fabscape could revolutionize data management in your fab operations.</p>

<p>Being a good data scientist is more than being able to create an ad-hoc model on a curated data set. 
To bring true value with ML means planning and implementing the architecture to ingest, store, process data, 
serve the model, monitor, and facilitate ongoing development.</p>

<p>Working in the Digital Transformation Department of Gigaphoton, I contributed to a flexible open data platform
to serve the strict security, hardware, and communication standards of the environment of the semiconductor Fab.</p>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Encoder decoder rnns for digital twin simulations</title><link href="https://jacobstrock.com/2023/11/25/Encoder-Decoder-RNNs-for-Digital-Twin-Simulations.html" rel="alternate" type="text/html" title="Encoder decoder rnns for digital twin simulations" /><published>2023-11-25T00:00:00+00:00</published><updated>2023-11-25T00:00:00+00:00</updated><id>https://jacobstrock.com/2023/11/25/Encoder%20Decoder%20RNNs%20for%20Digital%20Twin%20Simulations</id><content type="html" xml:base="https://jacobstrock.com/2023/11/25/Encoder-Decoder-RNNs-for-Digital-Twin-Simulations.html"><![CDATA[<p><img src="/assets/images/Post_Images/NewMethodsOldSeries/coastal_photo.jpg" alt="cross-covariance" /></p>

<h2 id="abstract">Abstract</h2>

<p>XXX</p>

<h2 id="poster">Poster</h2>

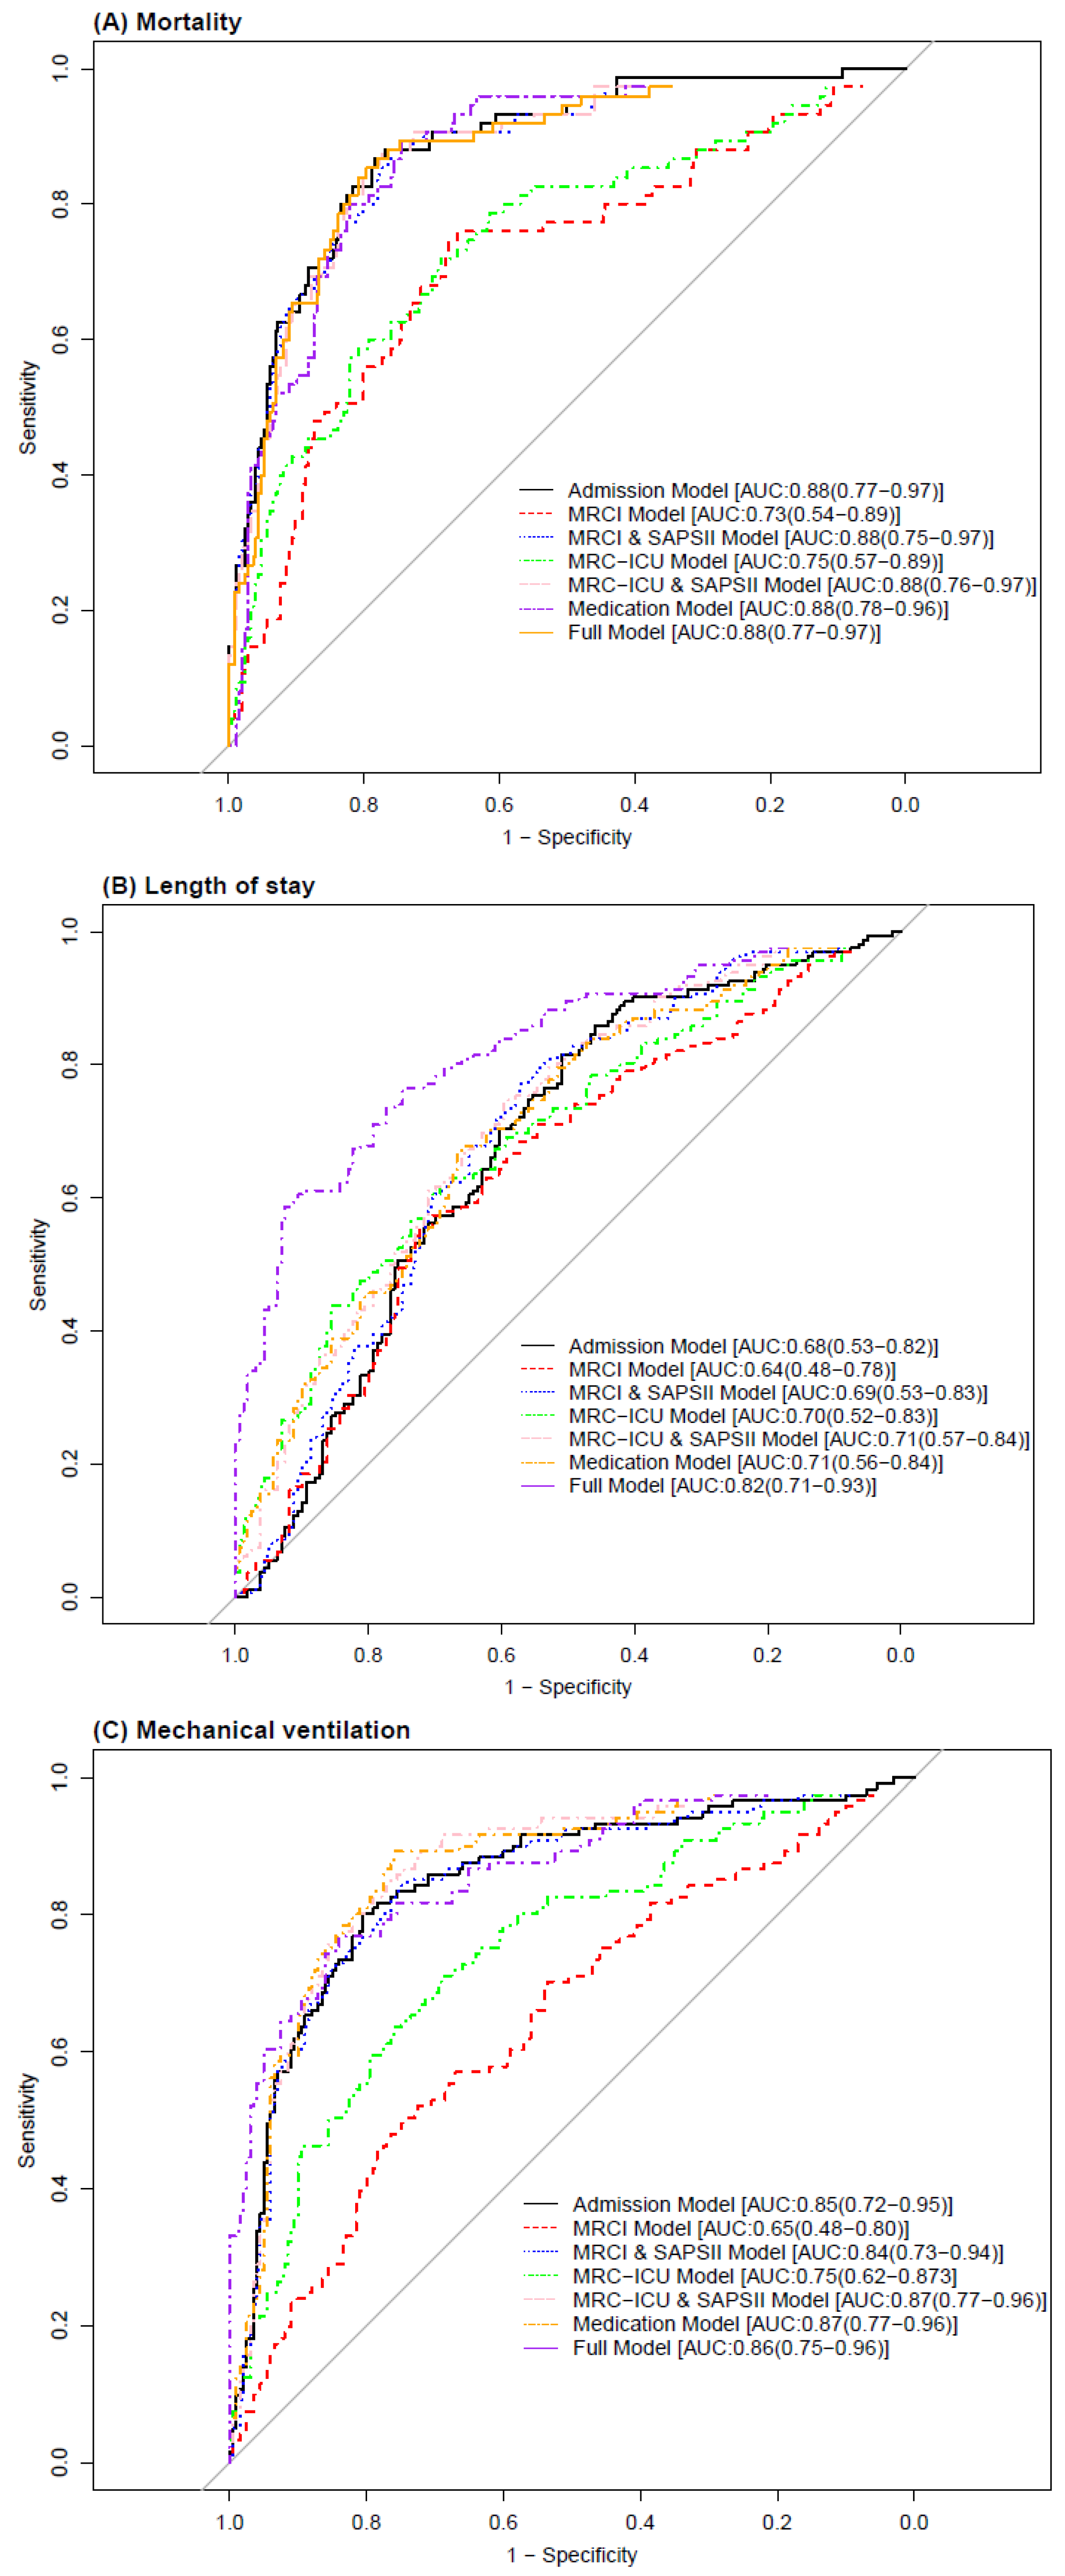
<h2 id="pdf">PDF</h2>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Medication regimen complexity to predict patient outcome</title><link href="https://jacobstrock.com/2023/06/18/Medication-Regimen-Complexity-to-Predict-Patient-Outcome.html" rel="alternate" type="text/html" title="Medication regimen complexity to predict patient outcome" /><published>2023-06-18T00:00:00+00:00</published><updated>2023-06-18T00:00:00+00:00</updated><id>https://jacobstrock.com/2023/06/18/Medication%20Regimen%20Complexity%20to%20Predict%20Patient%20Outcome</id><content type="html" xml:base="https://jacobstrock.com/2023/06/18/Medication-Regimen-Complexity-to-Predict-Patient-Outcome.html"><![CDATA[<p><img src="/assets/images/Post_Images/MedicationRegimenComplexity/jcm_sensitivity_specificity_mortality.png" alt="Sensitivity and specificity" /></p>

<p>Medication Regimen Complexity (MRC) may not be a term familiar to those outside of the medical field, yet in clinical circles, it plays an integral role in assessing a patient’s prescribed medications. MRC is a comprehensive evaluation that extends beyond merely tallying the number of medications. It delves into the specifics of each medication: the type, dosing frequency, and potential interactions. This deeper dive provides a holistic view of a patient’s health status and treatment trajectory. However, there is uncertainty as to the optimal metric, which translates to uncertainy in using these metrics for clinical decisions. It’s within this critical aspect of healthcare that I applied predictive classification models, aiming to unveil the predictive potential of MRC and its variants in determining patient outcomes.</p>

<p>Working alongside the clinical research experts Todd Brothers PhD, PharmD, and Mohammad Al-Mamun PhD, during my time at the Northeast Big Data and Innovation Hub, I used predictive models to evaluate the efficacy of two widely utilized MRC indices. Through these predictive analysis and other statistical comparisons, we explored the data to find the most effective metrics for predicting patient outcomes.</p>

<p>In this new project, I’ll show the power of bringing modeling techniques in healthcare analytics, for the application in MRC metrics. Although the sensitive nature of our data restricts me from sharing specifics or the precise analysis code, I will provide a thorough rundown of our methodological approach, the intriguing findings it yields, and the implications for future patient care.</p>
<object data="/assets/supplementaryfiles/JCM_MRCI_2022.pdf" width="1000" height="1000" type="application/pdf"></object>

<h2 id="objective">Objective:</h2>

<p>The objective of this study is to apply advanced statistical modeling techniques to assess and compare the predictive power of two commonly used Medication Regimen Complexity (MRC) indices for patient outcomes: MRCI &amp; MRC-ICU.</p>

<h2 id="data">Data:</h2>

<p>This study recieved all proper ethical approval (see publication details), and used deidentified, retrospective data.</p>

<p>The retrospective cohort study at Roger William Medical Center, Providence, Rhode Island, included 317 adult patients admitted to the intensive care unit (ICU) between 1 February 2020 and 30 August 2020. It included detailed information on patient demographics, laboratory measurements, vitals, medications, and outcome including time on mechanical ventilation, length of stay in the ICU and mortality.</p>

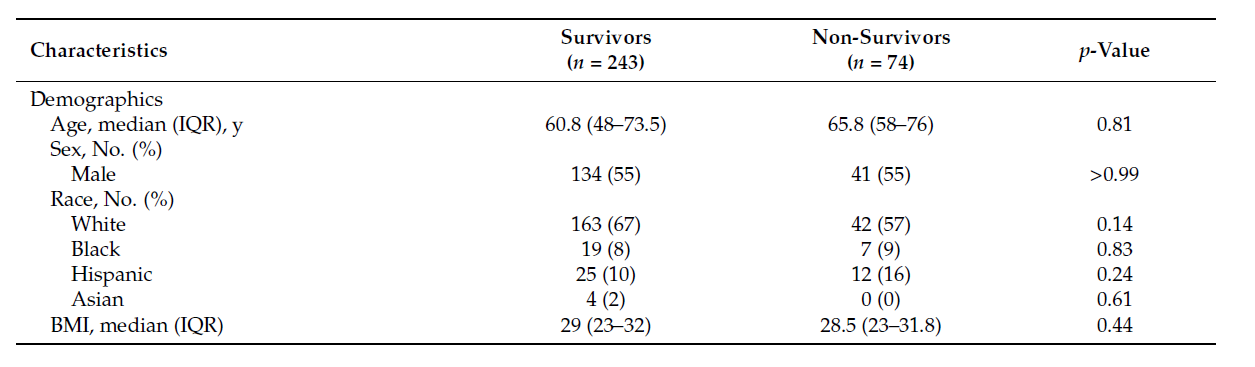
<p><img src="/assets/images/Post_Images/MedicationRegimenComplexity/jcm_table1.png" alt="Cohort Descriptive" /></p>

<h2 id="data-processing">Data Processing:</h2>

<p>MRCI and MRC-ICU were calculated according to the established criteria. We established cutoff values for both MRC scores based on their distribution within 24 hours of ICU admission. Since there are no standardized cutoff values specifically for critically ill patients, we selected the median values as our cutoff points. The “high” MRCI scoring cohort was defined as having scores greater than 63, while the “high” MRC-ICU cohort was defined as having scores greater than 6. We examined three clinical outcomes: mortality, length of stay (LOS), and the need for mechanical ventilation (MV) in the ICU. To assess LOS, we created a binary variable where LOS was labeled as 0 if it was less than 48 hours and 1 if it exceeded 48 hours. The need for MV was determined using a binary variable after 48 hours of ICU admission, with 0 indicating no mechanical ventilation and 1 indicating the use of mechanical ventilation. Hemodynamic instability was defined by the presence of hypotension (systolic blood pressure &lt; 100 mmHg), mean arterial pressure below 65 mmHg, or abnormal heart rate (arrhythmia or heart rate below 60 bpm or above 100 bpm).</p>

<p>Descriptive statistics were employed to summarize the study population, presenting continuous variables as means and interquartile ranges (IQRs), and categorical variables as frequencies and proportions. Student’s t-test, chi-squared (χ²) test, or Fisher’s exact test were used to compare clinical characteristics between survivor and non-survivor cohorts, as well as low- and high-MRC-scoring groups. Physiological and clinical characteristics were examined among the survivor and non-survivor cohorts, and severity scores (SAPS II, APACHE II, and CCI) were incorporated</p>

<h2 id="analysis--results">Analysis &amp; Results:</h2>

<p>To identify the predictors of clinical outcomes (mortality, length of stay [LOS], and need for mechanical ventilation [MV]), four multivariable logistic regression models were employed. These models included a combination of severity scores (APACHE II and SAPS II), Medication Regimen Complexity Index (MRCI), Medication Regimen Complexity in Intensive Care Unit (MRC-ICU), demographic variables, Charlson comorbidity index (CCI), and drug classes. Model I consisted of demographics, APACHE II, SAPS II, CCI, and 15 drug classes. Model II included demographics, MRCI at 24 hours and 48 hours, CCI, and drug classes. Model III incorporated demographics, MRC-ICU at 24 hours and 48 hours, CCI, and drug classes. Model IV encompassed all variables (refer to Table S3 for details). For the LOS models, MRCI and MRC-ICU values at 48 hours were excluded as the binary values were based on a 48-hour threshold after ICU admission. Significant predictors (p &lt; 0.05) were selected using a stepwise forward selection method.</p>

<p>Feature selection was performed using an L1 penalization technique called LASSO, which minimizes the influence of multicollinearity. The demographic variables considered were age, sex, height, weight, body mass index (BMI), and race. Odds ratios (OR) were calculated for each outcome of interest. All analyses were conducted using R software, specifically Version 4.0.0 (R Project for Statistical Computing), and implemented packages such as glm, glmnet, and ggplot2.</p>

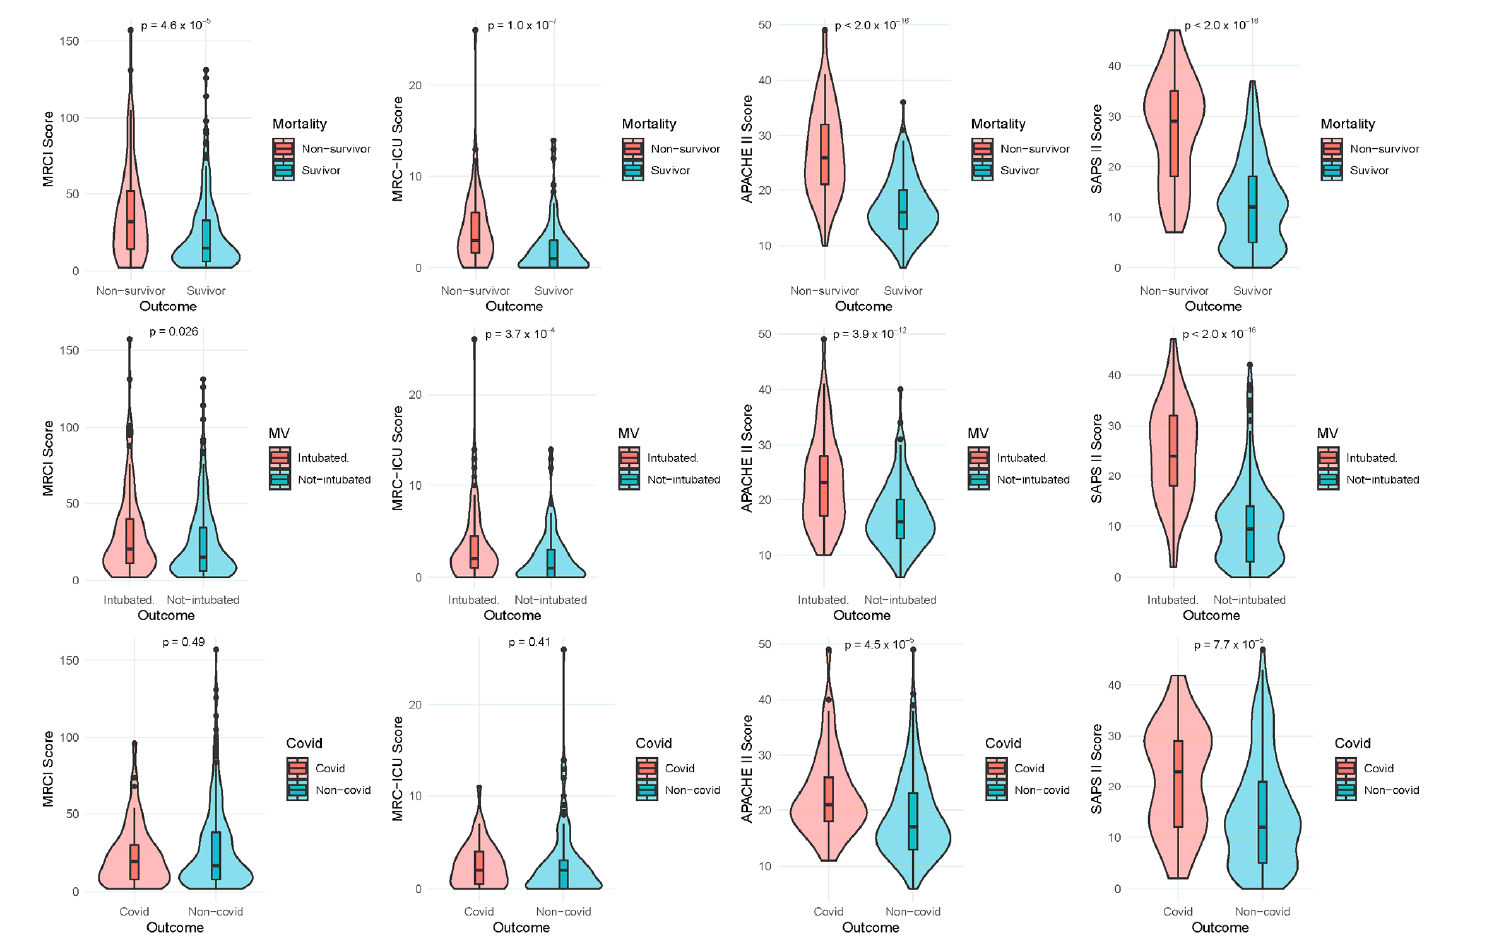
<p><img src="/assets/images/Post_Images/MedicationRegimenComplexity/jcm_violinplot.png" alt="Patient Classification" /></p>

<p>The MRC scores, both MRCI (Medication Regimen Complexity Index) and MRC-ICU (Medication Regimen Complexity in Intensive Care Unit), showed significant associations with critical outcomes like mortality, length of ICU stay (LOS), and the need for mechanical ventilation (MV). This was similar to APACHE II and SAPS II scores, which are designed to predict mortality risk and the severity of disease.</p>

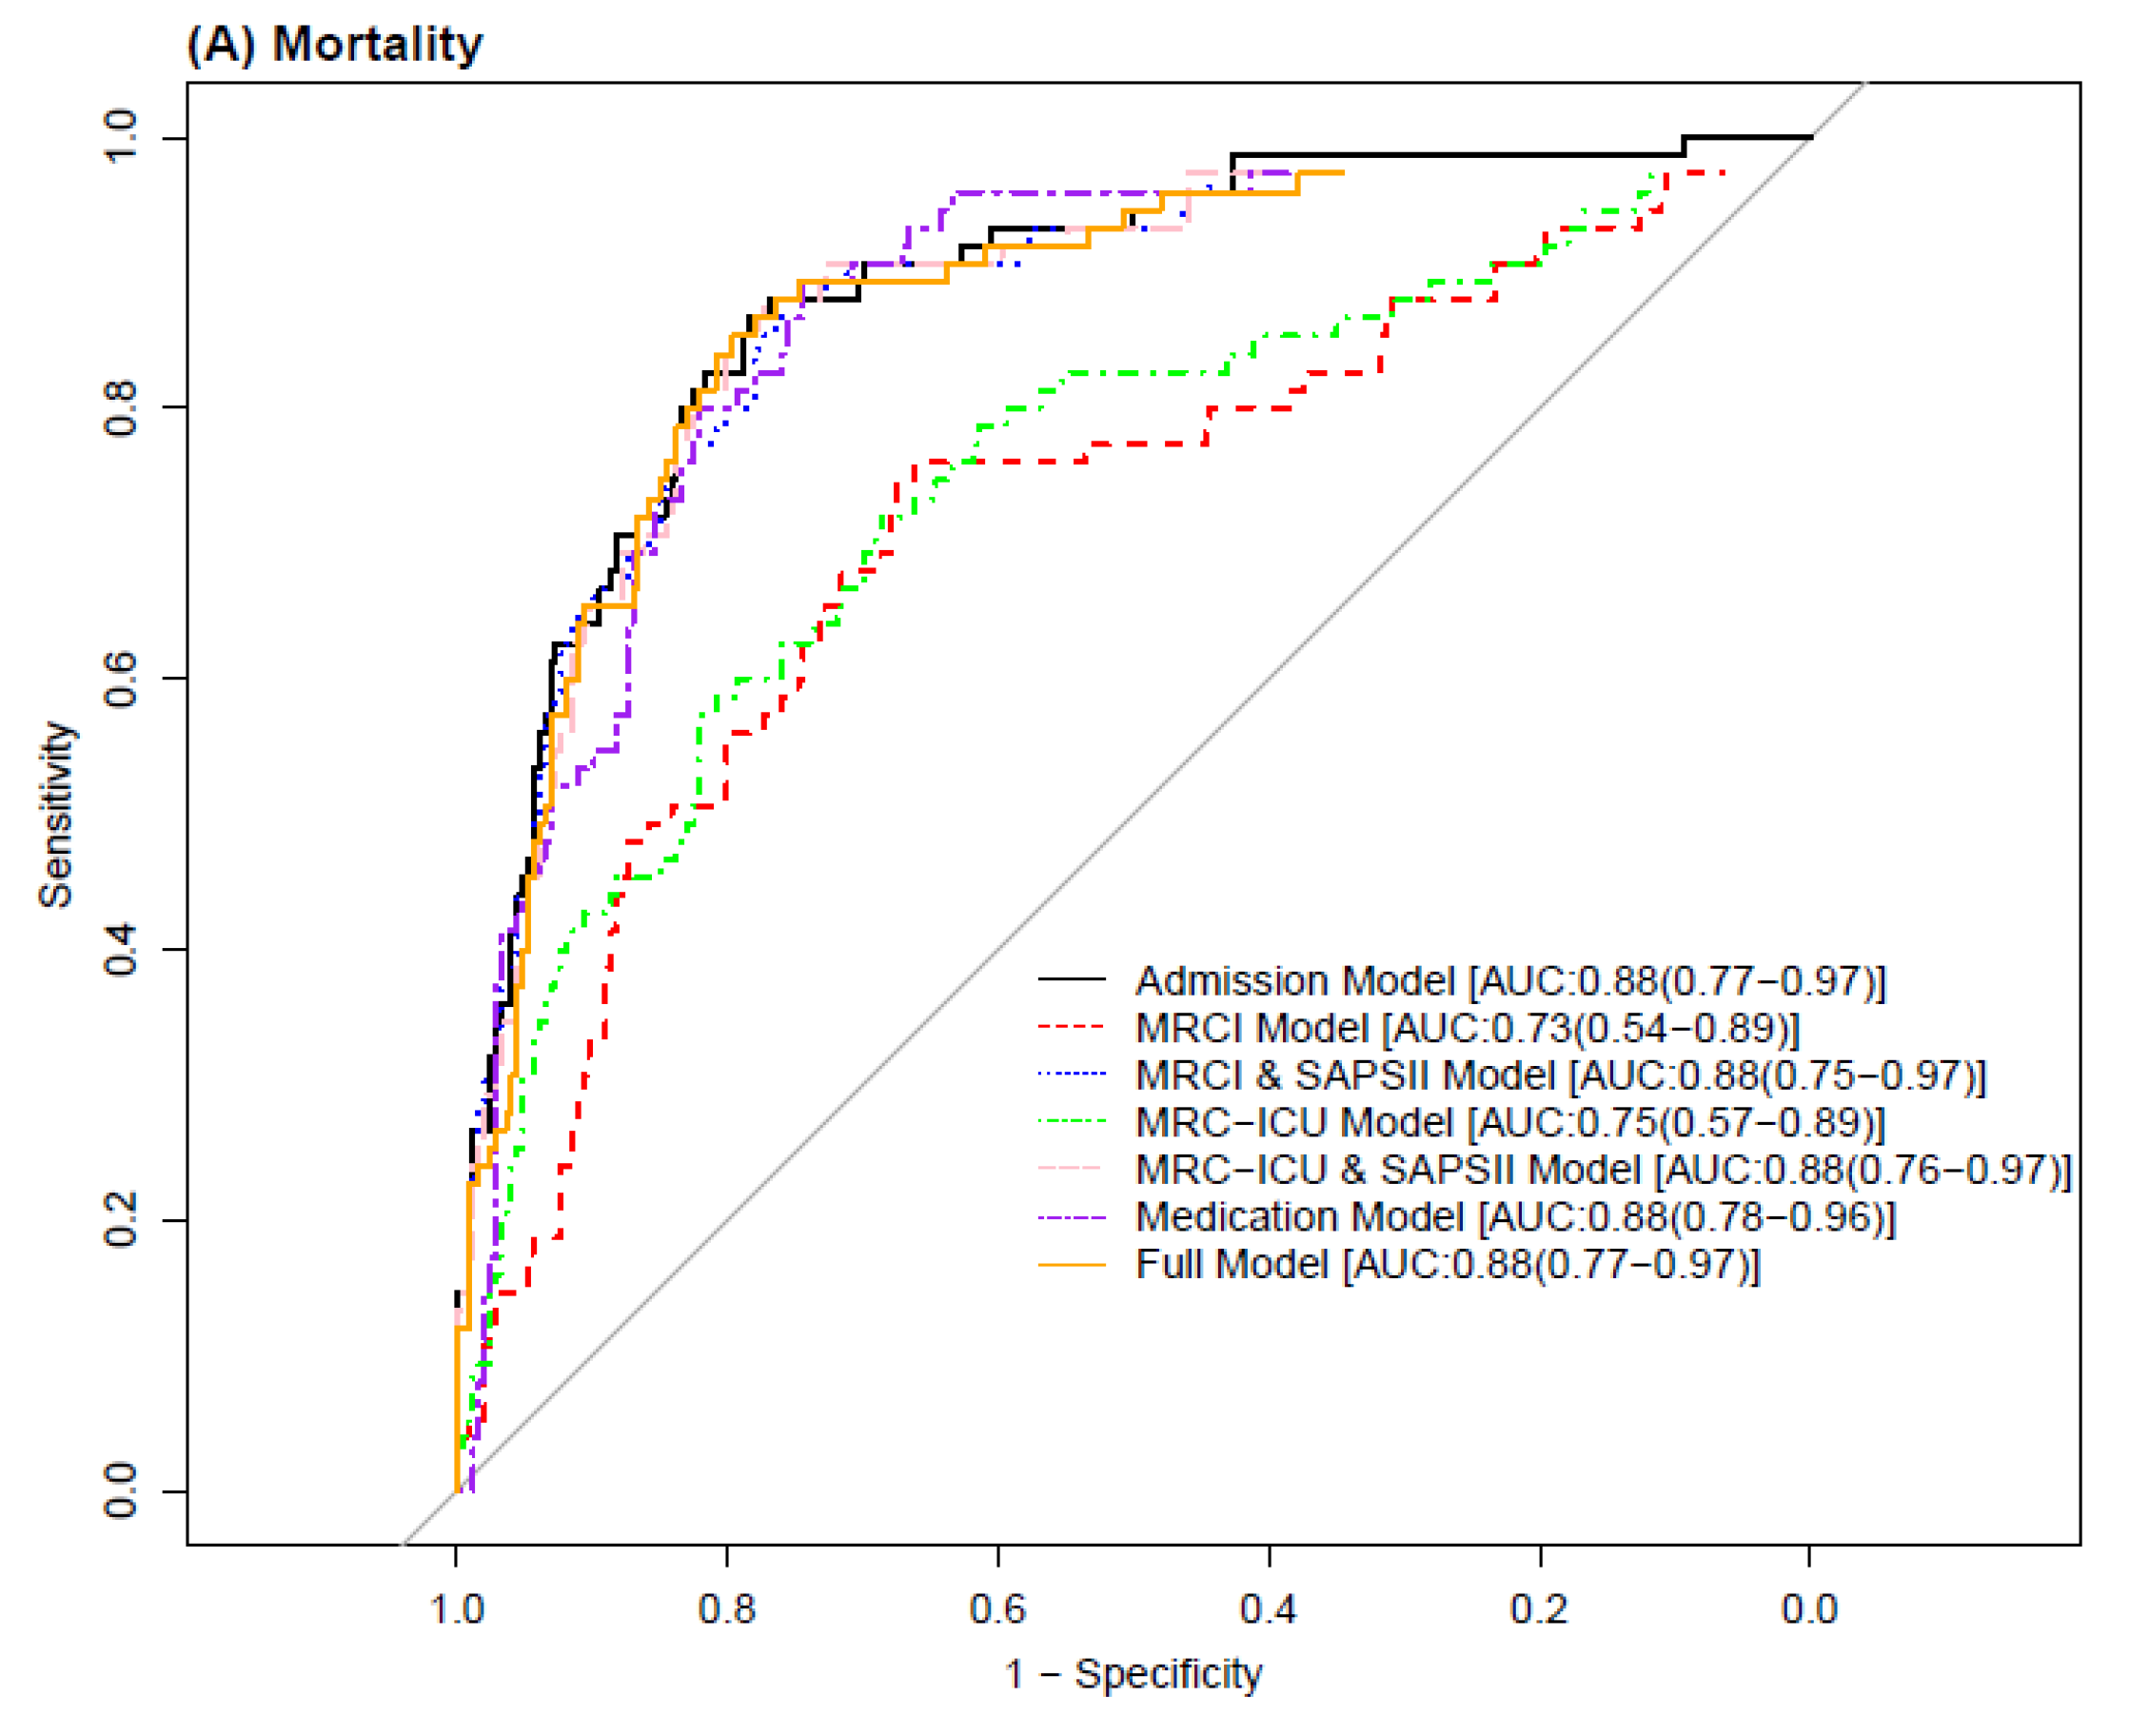
<p>To evaluate the prediction ability of MRC scores for mortality, LOS, and the need for MV, seven logistic classifier models were constructed without any variable selection. Correlation analysis was performed using the Pearson correlation coefficient, and the SAPS II severity score was chosen due to its high correlation with the APACHE II classification system (see Figure S1). The best-fit models were selected based on the best Akaike information criterion (AIC) measurement during cross-validation, employing an interactive process. All predictor variables were included in each prediction model setup to explicitly explore their individual roles. Model performance was assessed using the area under the receiver operating characteristic (ROC) curve (AUC), with an AUC of at least 0.7 considered acceptable. The models underwent a “leave-one-out” cross-validation method with 10,000 repetitions, and the AUC was selected as the overall performance measure. Sensitivity and specificity analyses were conducted for each of the three outcomes. Additionally, variable importance rankings were recorded for each clinical outcome in the prediction models.</p>

<p><img src="/assets/images/Post_Images/MedicationRegimenComplexity/jcm_sensitivity_specificity.png" alt="ROC" /></p>

<p>The ROC analysis revealed that models incorporating Medication Regimen Complexity (MRC) scores alongside traditional severity scores like APACHE II and SAPS II demonstrated comparable or slightly superior predictive power, as evidenced by AUC values. These findings highlight the added value of MRC scores in enhancing model accuracy not only for mortality but also for predicting the length of ICU stay and the necessity for mechanical ventilation, suggesting that MRC scores capture additional patient risk factors not fully accounted for by physiological and clinical measures alone.</p>

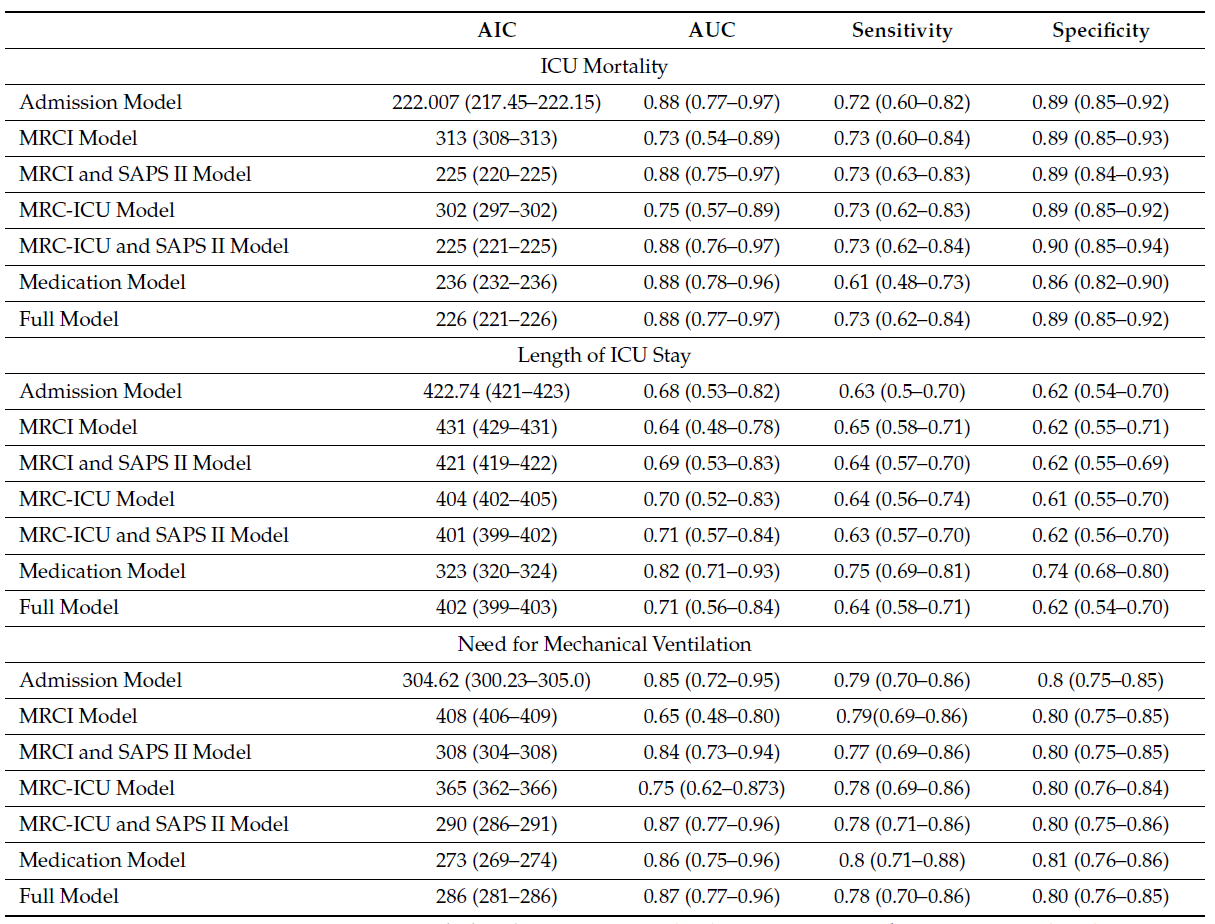
<p><img src="/assets/images/Post_Images/MedicationRegimenComplexity/jcm_table3.png" alt="Table 3" /></p>

<ul>
  <li>Both Medication Regimen Complexity Index (MRCI) and Medication Regimen Complexity in Intensive Care Unit (MRC-ICU) scores were significantly associated with clinical outcomes, including mortality, length of stay (LOS), and the need for mechanical ventilation (MV).</li>
  <li>Higher MRC scores were linked to hemodynamic instability and higher severity scores, such as APACHE II and SAPS II.</li>
  <li>Survivors had significantly lower MRCI, MRC-ICU, APACHE II, and SAPS II scores compared to non-survivors.</li>
  <li>The addition of MRC-ICU and SAPS II scores improved the prediction accuracy of clinical outcomes.</li>
  <li>Hispanic ethnicity was identified as an important variable in predicting mortality, LOS, and the need for MV.</li>
  <li>The use of vasopressors, pulmonary agents, paralytic agents, and psychiatric medications significantly influenced clinical outcomes.</li>
  <li>The study findings suggest that MRC scores can be valuable in identifying high-risk patients and optimizing clinical management.</li>
  <li>Logistic regression models and logistic classifier models demonstrated the predictive capabilities of MRC scores for patient outcomes.</li>
  <li>The L1 penalization technique (LASSO) was used for variable selection, minimizing multicollinearity and improving prediction accuracy.</li>
  <li>The study highlights the importance of incorporating MRC scores into standardized severity index scoring tools to enhance the prediction of critical care outcomes.</li>
</ul>

<h2 id="conclusions">Conclusions:</h2>

<ol>
  <li>
    <p>Medication Regimen Complexity (MRC) scores, including MRCI and MRC-ICU, are significantly associated with clinical outcomes, such as mortality, length of stay (LOS), and the need for mechanical ventilation (MV). These scores provide valuable insights into a patient’s health status and treatment course.</p>
  </li>
  <li>
    <p>Higher MRC scores are linked to hemodynamic instability, higher severity scores, and poorer clinical outcomes. Monitoring and managing medication regimens based on MRC scores can help identify patients at higher risk and optimize their care.</p>
  </li>
  <li>
    <p>Incorporating MRC scores, along with severity-of-illness scores like APACHE II and SAPS II, improves the accuracy of predicting clinical outcomes. This integration can enhance clinical decision-making and resource allocation in critical care settings.</p>
  </li>
  <li>
    <p>The use of specific medications, such as vasopressors, pulmonary agents, paralytic agents, and psychiatric medications, significantly influences patient outcomes. Understanding the impact of these medications can guide medication selection and management strategies to improve patient outcomes.</p>
  </li>
  <li>
    <p>The inclusion of MRC scores and medication-related factors in predictive models and statistical analysis provides valuable insights for clinicians and researchers. These models can assist in identifying high-risk patients, optimizing medication regimens, and improving patient-centered care.</p>
  </li>
  <li>
    <p>The study emphasizes the need for standardized MRC scoring and the integration of MRC scores into clinical decision support tools. By incorporating MRC scores into electronic health records and clinical workflows, healthcare professionals can receive alerts and recommendations for medication review and safer patient care.</p>
  </li>
  <li>
    <p>Future research should focus on validating the findings using larger patient cohorts and diverse populations. Additionally, exploring the role of MRC scores in specific high-acuity diseases and evaluating the impact of interventions based on MRC assessments would further enhance our understanding of medication regimen complexity and patient outcomes in critical care settings.</p>
  </li>
</ol>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">New methods for the oldest time series of its kind</title><link href="https://jacobstrock.com/2023/04/23/New-Methods-for-the-Oldest-Time-Series-of-Its-Kind.html" rel="alternate" type="text/html" title="New methods for the oldest time series of its kind" /><published>2023-04-23T00:00:00+00:00</published><updated>2023-04-23T00:00:00+00:00</updated><id>https://jacobstrock.com/2023/04/23/New%20Methods%20for%20the%20Oldest%20Time%20Series%20of%20Its%20Kind</id><content type="html" xml:base="https://jacobstrock.com/2023/04/23/New-Methods-for-the-Oldest-Time-Series-of-Its-Kind.html"><![CDATA[<p><img src="/assets/images/Post_Images/NewMethodsOldSeries/coastal_photo.jpg" alt="cross-covariance" /></p>

<p>There are two data attributes which are nearly ubiquitous but often under-appreciated and misunderstood. The first is time: a dimensions which is physically unavoidable, but often ignored to the detriment of predictive power and insight. The second is missing data: a true nuisance for analysis which can also easily become a major pitfall. This is especialy true if, as is often done, overly simplistic methods are relied on and thus major statistical bias introduced.</p>

<p>These ubiquitous and misunderstood attributes have fascinated me on countless projects, but stand forefront on analysis I developed working to unravel climate signals in a multi-decadal environmental series of environmental data. In this project, I looked to analyze how nutrient pollution had changed over decades in Narragansett Bay, across policy changes, and how this had affected the algae (aka phytoplankon) that make the base of the food-web, are responsible for eutrophication, and toxic bloom events.</p>

<p>Though the series is unprecidented in length (&gt;60 years to date), the data has major challenges that require careful design. Missing data is present throughout the series in some cases with durations &gt; 1 year, posing a challenge for unbiased inference. Further the changes to the underlying system, mean we expect the dependence structure evolves through time. Plainly, by this I mean coefficients, covariance, variance, etc. are unlikely to be static along the time dimension, and need to be able to change to describe changing relationships and structure.</p>

<p>Though, I will briefly summarize my work here, you can read my 133 page thesis about it (embedded below)…  or read my publication in <a href="https://www.intlpress.com/site/pub/pages/journals/items/sii/content/vols/0016/0003/a006/index.php?mode=ns">Statistics and Its Interface</a>, both of which will cover both greater breadth and depth.</p>

<object data="/assets/supplementaryfiles/INVESTIGATING LONG-TERM PHYSICAL CHEMICAL AND BIOLOGICAL CHANGES.pdf" width="1000" height="1000" type="application/pdf"></object>

<h2 id="objective">Objective:</h2>

<ol>
  <li>Identify the long-term patterns in key environmental traits &amp; identify the impact of policy change</li>
  <li>Characterize the seasonal and long-term dependence of algal growth on nutrients</li>
  <li>Develop a specialized architecture for inference with Bayesian dynamic linear models where missing data imputation is necessary and multiple modeling goals may be required</li>
</ol>

<h2 id="data">Data:</h2>

<p>The data for this study come from the University of Rhode Island, Long-term Narragansett Bay Monitoring Series (2003-2020). Within this period, from 2005-2012, Rhode Island law mandated a 50% reduction in nutrient pollution from coastal wastewater treatement centers, and a major question as to the efficacy of this action.</p>

<p>Temperature, NH<sub>4</sub> (ammonium), NO<sub>3</sub> + NO<sub>2</sub> (nitrate + nitrite), chlorophyl (chl) &lt;20 μm, chl &gt; 20 μm were the measured features of the series. The chemical variants of nitrogen are known pollutant types to affect algal growth, and the algae itself is measured via it’s dominant pigment (chlorophyl a). The algal measurements are divided on size because of the major effect of size on ecosystem function in everything from food-web interactions to carbon sequestration. Thus, through these measures we hope to see how relevant nutrient polution has changed, and the effect on algae.</p>

<h2 id="data-processing">Data Processing:</h2>

<p>The only processing taken before model development and fit is to perform a natural log transformation on nutrient and chlorophyll levels, simply to reduce skew in the data and meet Gaussian distribution assumptions for model errors. All other attributes with the data (e.g., missingingess, heteroskedasticity in time) I handled with the model architecture.</p>

<p><img src="\assets\images\Post_Images\NewMethodsOldSeries\RawData.png" alt="Raw Data" /></p>

<h2 id="analysis-and-results">Analysis and Results</h2>

<p>As described above, there are several key applied goals for the environmental series which are made difficult in particular by missing data. Ultimately, the technique I develop is with a multistage model where the first stage serves to analyze univariate time-series traits, and impute missing data with uncertainty, and a second stage is developed to target questions which are multivariate in nature (i.e., how algal biomass is affected seasonally and in the longterm by nutrient pollution).</p>

<h3 id="the-general-dlm-structure">The General DLM Structure</h3>

<p>The core of the modeling approach is the Bayesian dynamic linear model (or DLM), a popular time-series tools which model our data as observations of a latent state evolving through time according to an observation and state equation (eqns. 1, 2). These models have an inherent ability to imput missing data through forward filtering with the Kalman filter followed by backward sampling (Kalman 1960).</p>

<p><strong>Equation 1</strong>. Observation equation:</p>

\[Y_t = F_t \Theta_t + v,\quad v \sim N(0,V)\]

<p><strong>Equation 2</strong>. State equation:</p>

\[\Theta_t = G_t \Theta_{t-1} + w,\quad w \sim N(0, W)\]

<p><strong>Kalman Filtering and Smoothing</strong>:</p>

<ol>
  <li>
    <p>One-step-ahead predictive distribution of the latent state, \(f(\Theta_t \vert y_{1:t-1}) = N(a_t, R_t)\) where:</p>

\[a_t = E(\Theta_t|y_{1:t-1}) = G_t m_{t-1}\]

\[R_t = Var((\Theta_t|y_{1:t-1})) = G_t m_{t-1} G'_t + W_t\]
  </li>
  <li>
    <p>One-step-ahead predictive distribution of the observation, \(f(Y_t \vert y_{1:t-1}) = N(f_t, Q_t)\), where:</p>

\[f_t = E(Y_t \vert y_{t-1}) = F_t a_t\]

\[Q_t = Var(Y_t \vert y_{t-1}) = F_t R_t F'_t + V_t\]
  </li>
  <li>
    <p>The filtered distribution of the latent state, \(f(\Theta_t \vert y_{1:t}) = N(m_t, C_t)\), where:</p>

\[m_t = E(\Theta_t \vert y_{1:t}) = a_t + R_t F'_t Q^{-1}_t e_t\]

\[C_t = Var(\Theta_t \vert y_{1:t}) = R_t - R_t F'_t Q'_t F_t R_t\]

\[e_t = Y_t - f_t\]
  </li>
  <li>
    <p>The smoothed distribution of the latent state, \(f(\Theta_t \vert y_{1:T})=N(s_t, S_t)\), where:</p>

\[s_t = E(\Theta_t \vert y_{1:T}) = m_t + C_t G'_{t+1} R'_{t+1}(s_{t+1} - a_{t+1})\]

\[S_t = C_t - C_t G'_{t+1}R^{-1}_{t+1}(R_{t+1})R^{-1}_{t+1}G_{t+1}C_t\]
  </li>
</ol>

<p>These models also allow any parameter of our model to time vary, allowing us to study temporally changing relationships. This includes covariance matrices through a method called discount factoring. This method works extremely well for dynamic covariance when data are mostly complete. The method, outlined in West and Harrison 1997, mathematically suggest that the covariance matrix \(W_t\) for the latent state specification of the model, should decay from one time step to the next.</p>

<p>The DLM itself, like a NN or regression is just a general framework to which we can adapt to very specific architecture. Through the general system of equations shown above, very detailed solutions are possible, for example, ARIMAX or dynamic regression are popular architectures. In our case, we build architectures specifically to answer our questions in each of the stages.</p>

<h3 id="stage-1-architecture">Stage 1 Architecture</h3>

<p>In stage 1, we setout to answer questions about long-term patterns such as seasonality, and the long-term trend. Thus we can build a structure which specifically includes these components. In the parameterization outlined below, each time-series is modeled with a dynamic intercept (long-term trend, \(\mu\)), and Fourier form seasonal components from a period of 1 year to 23 weeks to capture complex seasonal patterns.</p>

\[F_i^Q = [1,\ (1,\ 0),\ (1,\ 0),\ ...\, (1,\ 0)_J]\]

\[G_i^Q = \begin{bmatrix} 1 &amp; \\\  &amp; G_s^Q \end{bmatrix}\]

\[G_s^Q = \begin{bmatrix} H_1 &amp; &amp; \\\ &amp; \ddots &amp; \\\ &amp; &amp; H_J \end{bmatrix}\]

\[H_j = \begin{bmatrix} cos(\omega_j) &amp; sin(\omega_j)\\\ -sin(\omega_j) &amp; cos(\omega_j) \end{bmatrix}\]

\[\omega_j = 2\pi_j/s, j=1, ..., J\]

\[\theta_{i,t}^Q = \begin{bmatrix} \mu_i \\\ S_{i,1,t} \\\ S_{*i,1,t} \\\
\vdots \\\ S_{i,J,t} \\\ S_{*i,J,t} \end{bmatrix}\]

<h3 id="stage-2-architecture">Stage 2 Architecture</h3>

<p>In the second stage, the goals is to determine the dependence structure between nutrients and algal biomass. Rather than try to model the series entirely with trend and seasonal components, we try to quantify the impact of an exogenous predictor. The second stage model also includes a dynamic intercept, a annual cycle with a period of 1 year, and a dynamic regression component on nitrogen sources. In this way, the model tells us how nitrogen predicts the anomaly from bulk seasonal and long-term patterns which are affected by a plethora of other traits.</p>

\[F_Z = [1, g(X),\ (1,\ 0)]\]

\[G_Z = \begin{bmatrix} 1 &amp; &amp; \\\ &amp; 1 &amp; \\\ &amp;  &amp; G_s^Z \end{bmatrix}\]

\[G_s^Q = H\]

\[H_j = \begin{bmatrix} cos(\omega_j) &amp; sin(\omega_j)\\\ -sin(\omega_j) &amp; cos(\omega_j) \end{bmatrix}\]

\[\omega_j = 2\pi/s\]

\[\theta_{i,t}^Q = \begin{bmatrix} \mu_{i, t} &amp; \dots &amp; \mu_{z,t}\\\ 
\beta_{1,t} &amp; \dots &amp; \beta_{1,t} \\\
S_{i,t} &amp; \dots &amp; S_{z,t} \\\ 
S_{*i,t} &amp; \dots &amp; S_{*z,t} \end{bmatrix}\]

<h2 id="model-fit">Model Fit</h2>

<p>The model was fit with Markov-chain monte-carlo to solve for the posterior distribution of each parameter. It’s worth noting that the method of dividing the modeling into two stages allowed the MCMC inference to be carried out independently for each stage. This separation meant that the posteriors from stage 1 could be sampled in stage 2, and the inference on missing data did not need to be repeated in the regression analysis. This added efficiency to the model fitting process.</p>

<h3 id="results">Results</h3>

<p>The study presents a two-stage Dynamic Linear Model (DLM) as a versatile tool for handling noisy, incomplete, and non-monotonic time-series data in long-term environmental monitoring. In this work:</p>

<ul>
  <li>I successfully applied a new multistage DLM architecture to assess the relationship between phytoplankton populations and dissolved inorganic nitrogen (DIN) levels in the Narragansett Bay.</li>
  <li>The first stage of the model allows characterization of seasonal and long-term change in the data and supports inference into periods of missing data. The completed data series helps in further exploratory analysis.</li>
</ul>

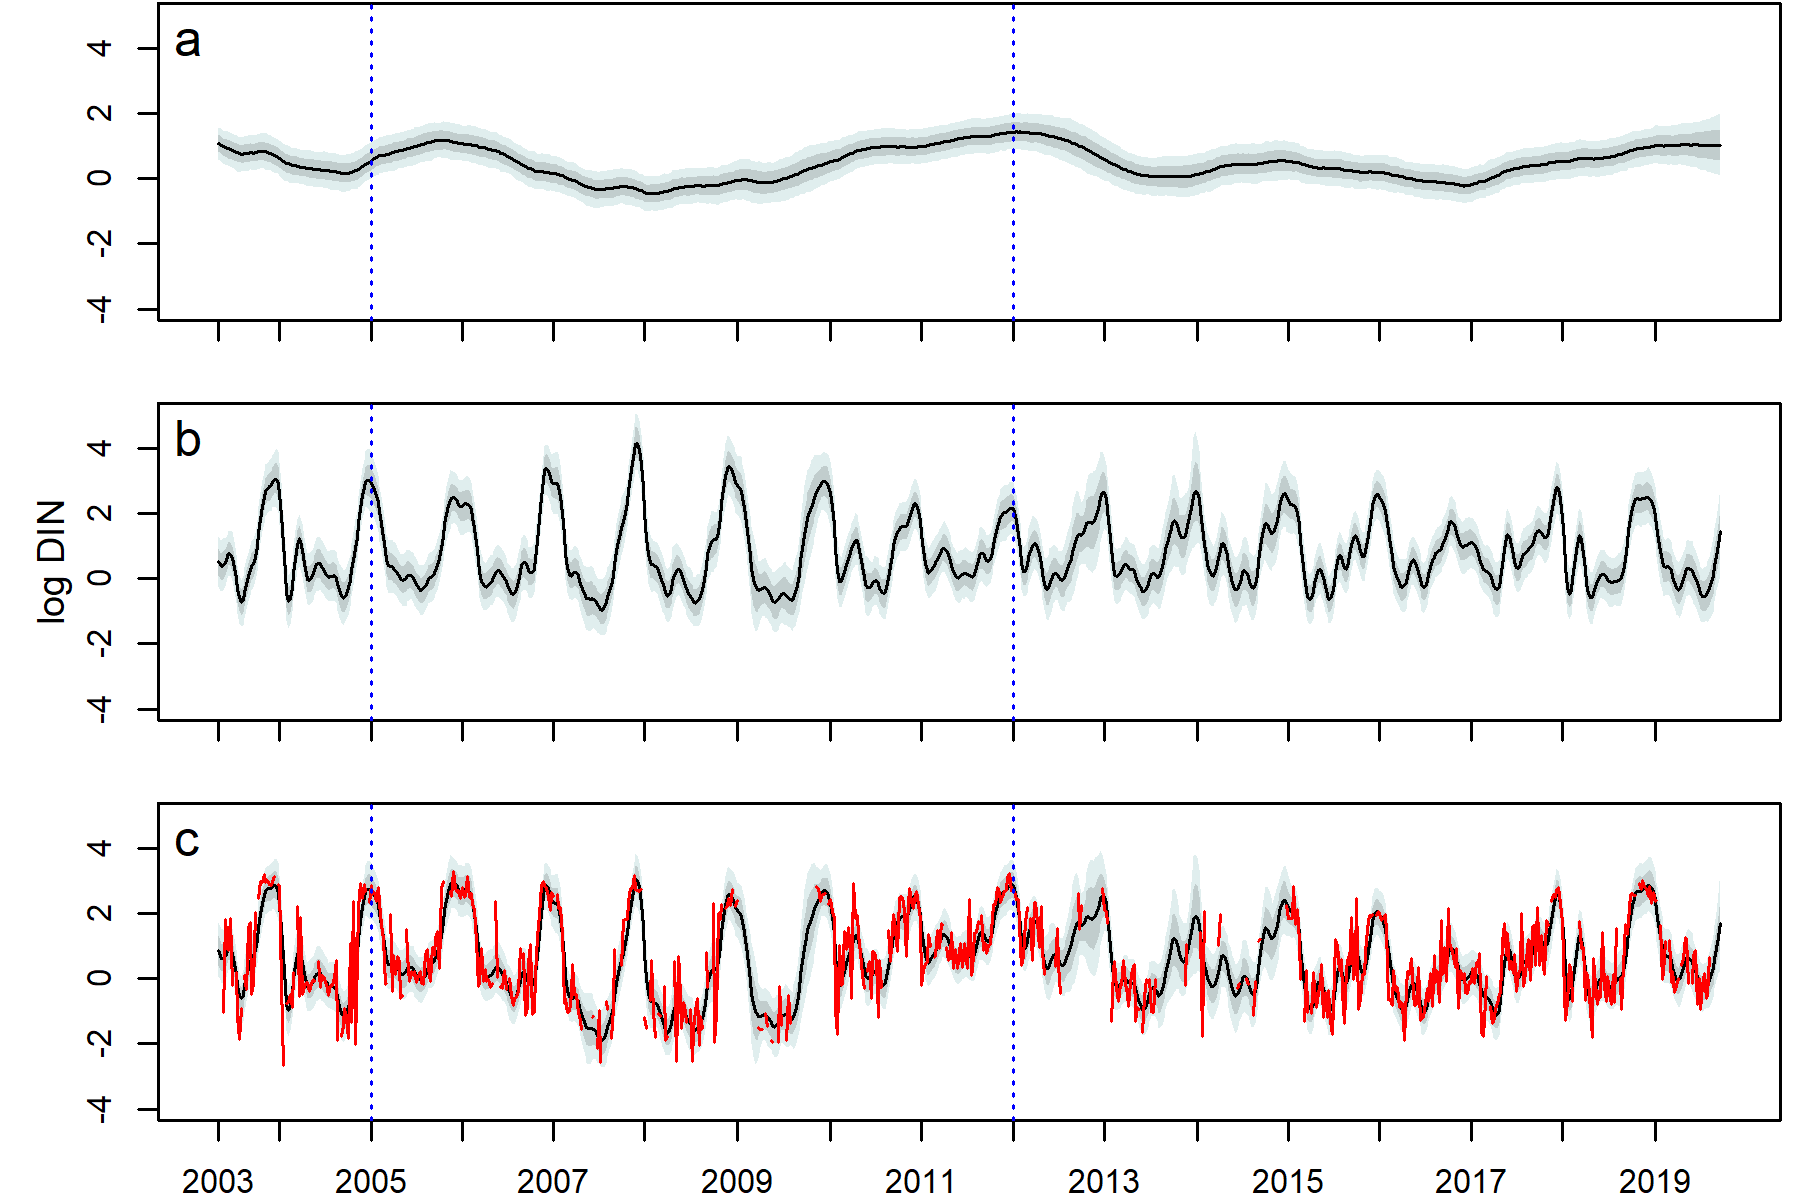
<p><img src="/assets/images/Post_Images/NewMethodsOldSeries/DINDLM.png" alt="Alt text" /></p>
<p align="center"><i>Decomposition of the DIN series DLM
(2003–2019), fit with the stage 1 model structure. a. the
dynamic intercept, b. the seasonal trend, c. the posterior
predicted mean with the true data (red). The median (black),
80% (dark grey shading), and 95% (light grey shading)
pointwise credible intervals are shown. Blue dotted lines
denote the beginning and end years of policy mandated
nutrient remediation.</i></p>

<ul>
  <li>The second stage of the model focuses on dynamic regression, working with the latent levels of the predictors, which are devoid of observational uncertainty. This stage examines the dependencies between the studied variables.</li>
</ul>

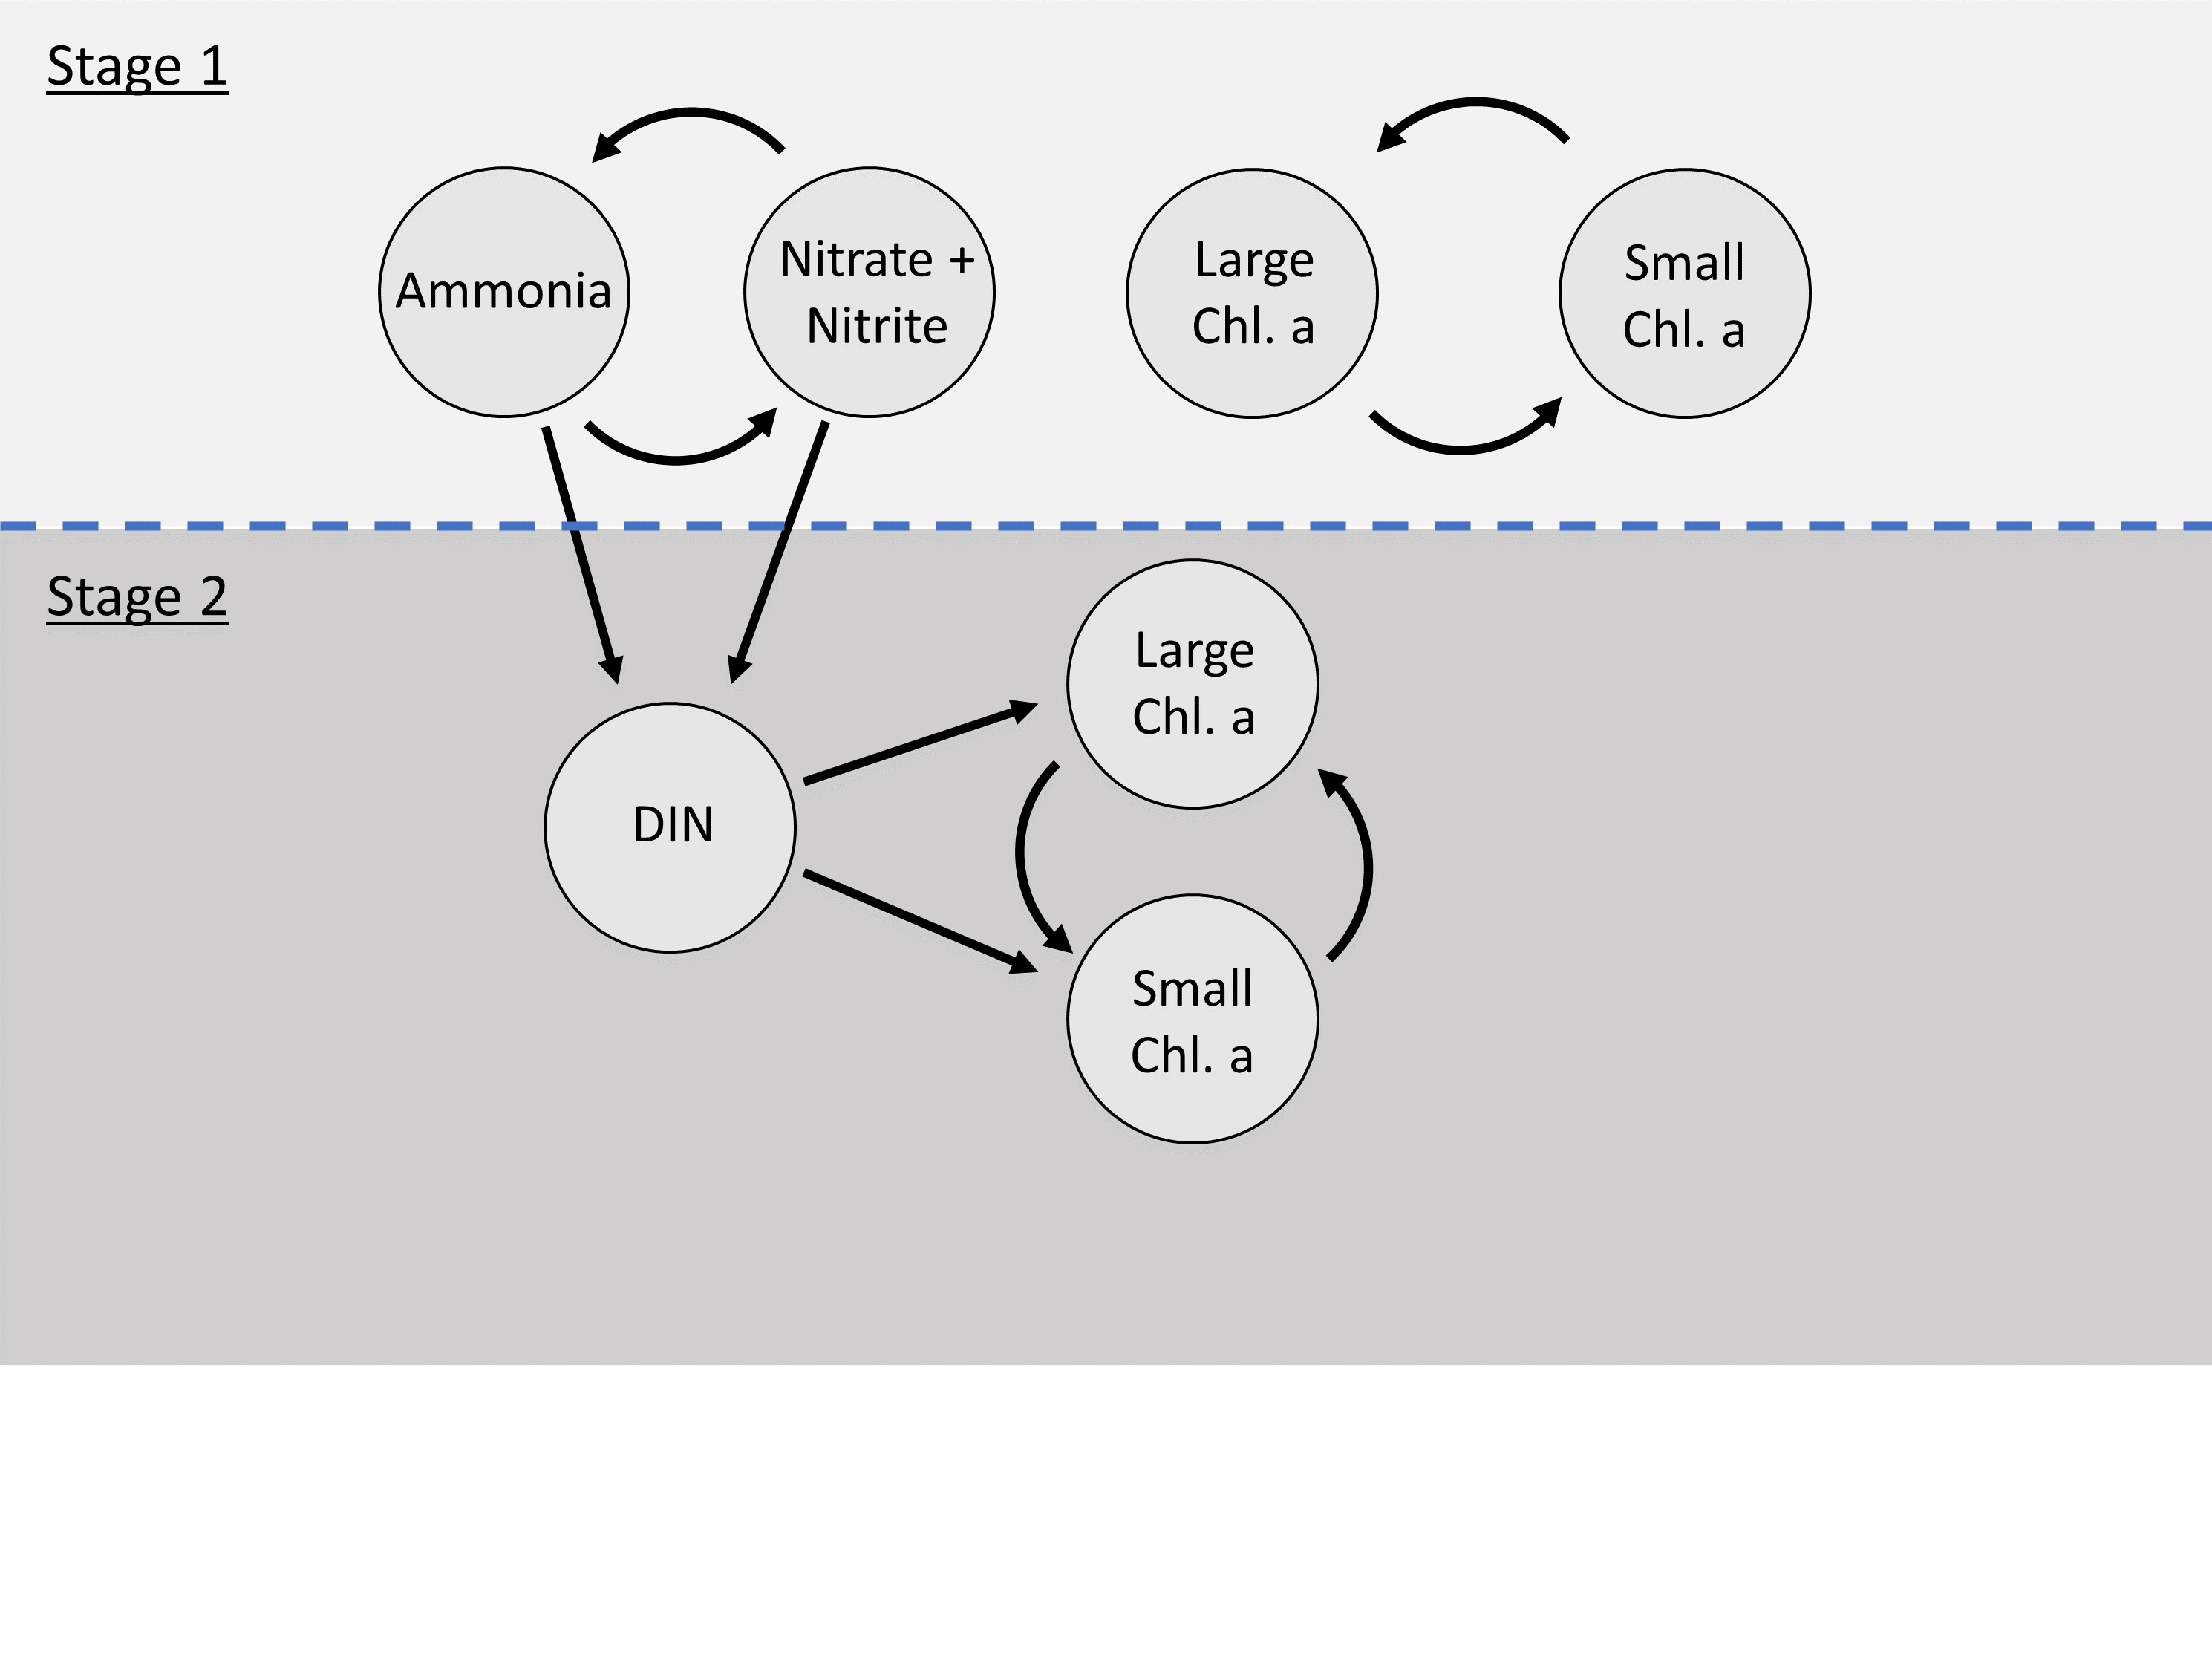
<p><img src="/assets/images/Post_Images/NewMethodsOldSeries/DiagramPPT_v2.png" alt="Alt text" /></p>
<p align="center"><i>Dependence structure between components of the
stage 1 and stage 2 model for the Narragansett Bay
ecological model. A bivariate model was run for small and
large chl. a as well as nitrate + nitrite to describe long-term
patterns among all series. Examination of prewhitened
cross-correlations between the imputed series after stage 1 led
to the use of DIN as a predictor in stage 2 to explore the
influence of nitrogen on size structure of phytoplankton.
Stage 2 used latent levels of
ammonia and nitrate + nitrite.</i></p>

<ul>
  <li>
    <p>Practical discount methods were found critical for the evolution covariance matrix, preventing over-parameterization and mixing issues in the Markov Chain Monte Carlo (MCMC) algorithm, which is used for estimation and inference in the DLM.</p>
  </li>
  <li>
    <p>The multistage DLM allows for the MCMC inference to be carried out independently for each stage, improving computational efficiency by not repeating the inference on missing data in the regression analysis.</p>
  </li>
  <li>
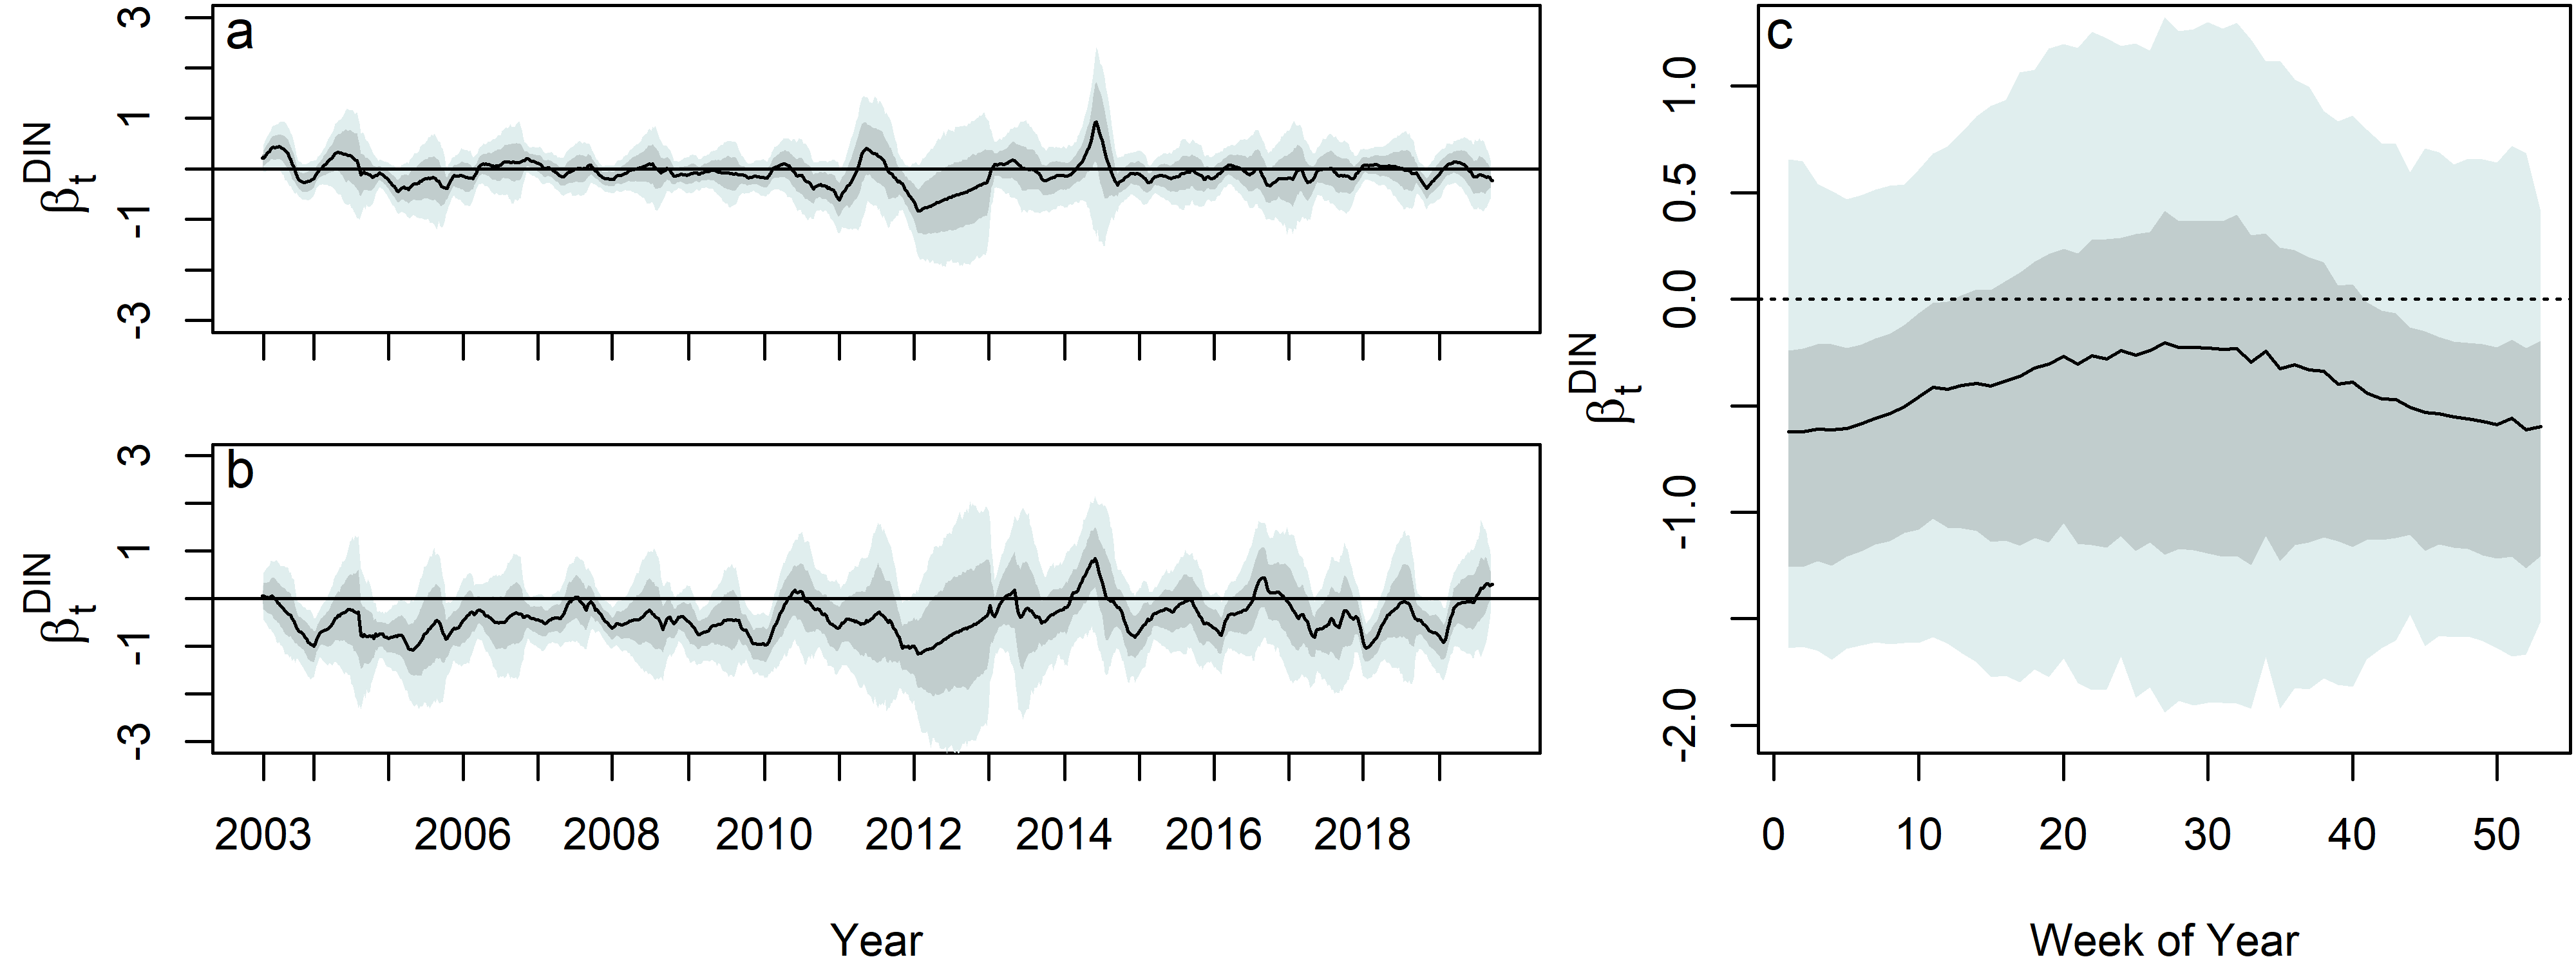
    <p>Ultimately, this model answered the key question on how algae blooms were effected by the policy changes. Results suggest that smaller phytoplankton (&lt;20 μm) are relatively unaffected by changes in DIN levels, while larger phytoplankton (&gt;20 μm) show a negative relationship with DIN. This relationship varies seasonally, with the strongest associations occurring in the winter.</p>
  </li>
</ul>

<p><img src="/assets/images/Post_Images/NewMethodsOldSeries/BetaCompare.png" alt="Alt text" /></p>
<p align="center"><i>The dynamic regression coefficient, $\beta^{DIN}_t$ , for both the a. Small chl. a series b. Large chl. a series. c. Posterior
distribution of the dynamic regression coefficient, $\beta^{DIN}_t$ , on DIN for the large chl. a, plotted by week on the x–axis, and by
year as denoted by color shading. The median (black), 80% (dark grey shading), and 95% (light grey shading) are shown.</i></p>

<ul>
  <li>
    <p>The multistage DLM can accommodate data with significant missing points, disparate data streams, and multiple modeling goals.</p>
  </li>
  <li>
    <p>The multi-stage state-space model architecture shows value for environmental monitoring and similar long-term analyses.</p>
  </li>
</ul>

<h2 id="conclusions">Conclusions:</h2>

<ul>
  <li>
    <p>Policy changes did not have a statistically distinguishable effect on Nitrogen levels at the study site (though other research has found localized effects closer to the sources).</p>
  </li>
  <li>
    <p>The size of algal organisms shifted from being dominated by large to being dominated by small organisms, which could potentially impact everything from food-web structures to carbon sequestration.</p>
  </li>
  <li>
    <p>The dependence on nitrogen has not significantly changed, and is highly seasonal, meaning seasonally targeted efforts, especially in the winter could have the greatest effect on algal growth.</p>
  </li>
  <li>
    <p>Practical discounting methods, though previously untested, show superior accuracy for imputation in cases of non-static covariance.</p>
  </li>
  <li>
    <p>The multi-stage architecture is particularly advantageous for modeling efforts with multiple goals and extensive missing data. With this architecture, the first stage can server to both characterize the time-series and provide advanced multiple imputation, leaving the flexibility to experiment in the second stage with a more parsimonious model.</p>
  </li>
</ul>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">An improved method for missing data in time series</title><link href="https://jacobstrock.com/2022/07/24/An-Improved-Method-for-Missing-Data-in-Time-Series.html" rel="alternate" type="text/html" title="An improved method for missing data in time series" /><published>2022-07-24T00:00:00+00:00</published><updated>2022-07-24T00:00:00+00:00</updated><id>https://jacobstrock.com/2022/07/24/An%20Improved%20Method%20for%20Missing%20Data%20in%20Time%20Series</id><content type="html" xml:base="https://jacobstrock.com/2022/07/24/An-Improved-Method-for-Missing-Data-in-Time-Series.html"><![CDATA[<p>Time series analysis is the topic that has gripped me since I started studying statistics. Who doesn’t want to better understand the past and predict the future? Most of the data that is collected has a time component which is non-negligable. While some consider the non-independence of data a nuissance for statistical analysis, I consider it one of the greatest opportunities to understand the time pattern.</p>

<p>Time series analysis and time series of data are powerful for building our understand on a topic, but there is almost invariably a big challenge: missing data. Measuring devices brake, data collection is interupted, and periodically the funding may dry up. The way that we handle this missing data can have large effects and potential biases for our inference.</p>

<p>Bayesian state-space models and the particular case of the dynamic linear model are popular time-series tools which model our data as observations of a latent state evolving through time according to an observation and state equation (eqns. 1, 2). These models have an inherent ability to imput missing data through forward filtering with the Kalman filter followed by backward sampling (Kalman 1960).</p>

<p><strong>Equation 1</strong>. Observation equation:</p>

\[Y_t = F_t \Theta_t + v,\quad v \sim N(0,V)\]

<p><strong>Equation 2</strong>. State equation:</p>

\[\Theta_t = G_t \Theta_{t-1} + w,\quad w \sim N(0, W)\]

<p><strong>Kalman Filtering and Smoothing</strong>:</p>

<ol>
  <li>
    <p>One-step-ahead predictive distribution of the latent state, \(f(\Theta_t \vert y_{1:t-1}) = N(a_t, R_t)\) where:</p>

\[a_t = E(\Theta_t|y_{1:t-1}) = G_t m_{t-1}\]

\[R_t = Var((\Theta_t|y_{1:t-1})) = G_t m_{t-1} G'_t + W_t\]
  </li>
  <li>
    <p>One-step-ahead predictive distribution of the observation, \(f(Y_t \vert y_{1:t-1}) = N(f_t, Q_t)\), where:</p>

\[f_t = E(Y_t \vert y_{t-1}) = F_t a_t\]

\[Q_t = Var(Y_t \vert y_{t-1}) = F_t R_t F'_t + V_t\]
  </li>
  <li>
    <p>The filtered distribution of the latent state, \(f(\Theta_t \vert y_{1:t}) = N(m_t, C_t)\), where:</p>

\[m_t = E(\Theta_t \vert y_{1:t}) = a_t + R_t F'_t Q^{-1}_t e_t\]

\[C_t = Var(\Theta_t \vert y_{1:t}) = R_t - R_t F'_t Q'_t F_t R_t\]

\[e_t = Y_t - f_t\]
  </li>
  <li>
    <p>The smoothed distribution of the latent state, \(f(\Theta_t \vert y_{1:T})=N(s_t, S_t)\), where:</p>

\[s_t = E(\Theta_t \vert y_{1:T}) = m_t + C_t G'_{t+1} R'_{t+1}(s_{t+1} - a_{t+1})\]

\[S_t = C_t - C_t G'_{t+1}R^{-1}_{t+1}(R_{t+1})R^{-1}_{t+1}G_{t+1}C_t\]
  </li>
</ol>

<p>These models also allow any parameter of our model to time vary, allow us to study temporally changing relationships. This includes covariance matrices through a method called discount factoring. This method works extremely well for dynamic covariance when data are mostly complete. The method, outlined in West and Harrison 1997, mathematically suggest that the covariance matrix \(W_t\) for the latent state specification of the model, should decay from one time step to the next.</p>

<p><strong>Discounting Covariance</strong>:</p>

\[R_t = Var(\Theta_t \vert y_{1:t-1}) = G_t C_{t-1} G'_t + W_t\]

\[R_t = P_t + W_t\]

\[W_t = \frac{1-\delta}{\delta}P_t\]

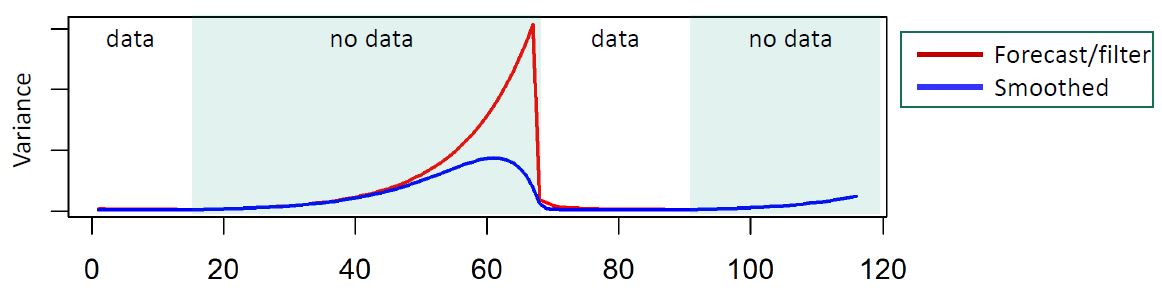
<p>Practically, this equation represents how the information is lost from one time step to the next.</p>

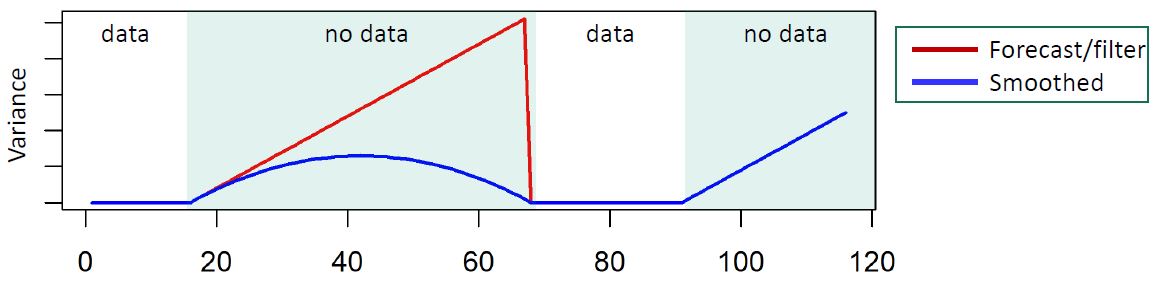
<p>The issue is that for data with extended periods of missingness, standard discounting methods would have the loss of information grow at an exponential rate in the forward filter. If we are predicting \(k\) steps ahead with data, then the covariance at step \(k\) ahead becomes:</p>

\[C_t(k) = \frac{G^k C_t G'^{k}}{\delta^k}\]

<p><img src="/assets/images/Post_Images/Imputation_exponentialloss.JPG" alt="exponential loss" /></p>

<p>This is as opposed to a linear rate in a static covariance specification that comes with the Kalman filter above:</p>

<p><img src="/assets/images/Post_Images/Imputation_linearloss.JPG" alt="linear loss" /></p>

<p>Inutition suggests that an exponential loss of information in missing data may be overly conservative, but what covariance specification gives us the most accurate results for periods of extensive missing data?</p>

<p>Further, what is the optimal selection criteria for selecting a discount factor?</p>

<object data="/assets/supplementaryfiles/NESS_presentation_Final.pdf" width="1000" height="1000" type="application/pdf"></object>

<h2 id="objectives">Objectives:</h2>

<ol>
  <li>
    <p>Identify the optimal discounting strategy for prolonged periods of missingness</p>
  </li>
  <li>
    <p>Identify the criteria with the strongest statistical power to compare models with different configurations such as fixed discount factors.</p>
  </li>
</ol>

<h2 id="data-">Data :</h2>

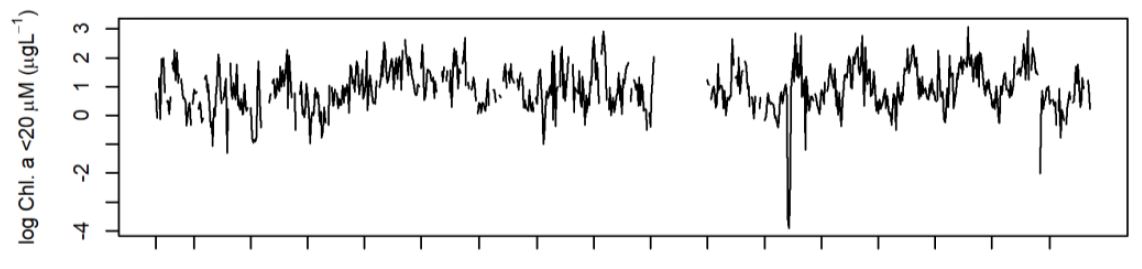
<p>This theoretical investigation was spurred by real time series data from the Narragansett Bay Long-term Time Series. I will use the log transformed Chlorophyll (algal pigment data), because it is the subject of another time series analysis I have been working on. The data is from 2003 to 2020, collected at weekly resolution. While the use of a multivariate analysis would be optimal for imputation, I use a univariate series to focus on the question of covariance specification.</p>

<p>Raw data can be found <a href="https://web.uri.edu/gso/research/plankton/">here</a>.</p>

<p><img src="/assets/images/Post_Images/Imputation_rawdata.JPG" alt="Raw data" /></p>

<h2 id="data-processing">Data Processing:</h2>

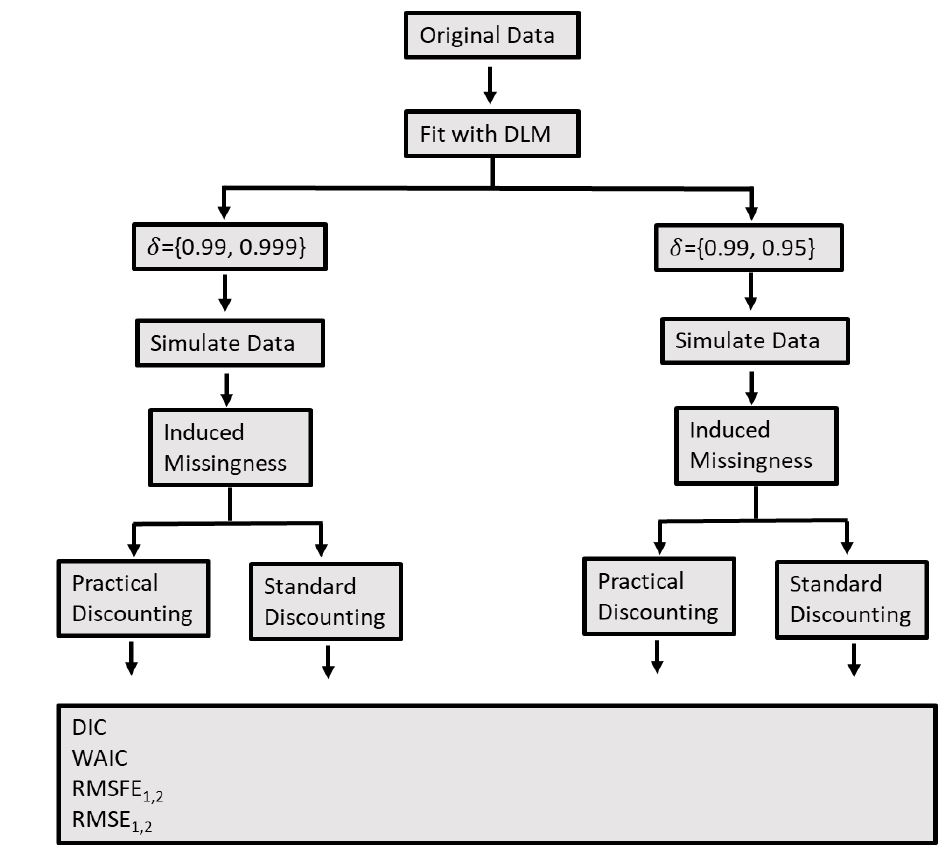
<p>While it might seem counter-intuitive, I am using the real data from the time-series to parameterize known data generation models. I choose to do this over completely random data generation models becuase this theoretical investigation is directly tied to the applied problem of analyzing the real data with heteroskedastic behavior and prolonged missingness.</p>

<p><img src="/assets/images/Post_Images/Imputation_flowchart.JPG" alt="Flow chart" /></p>

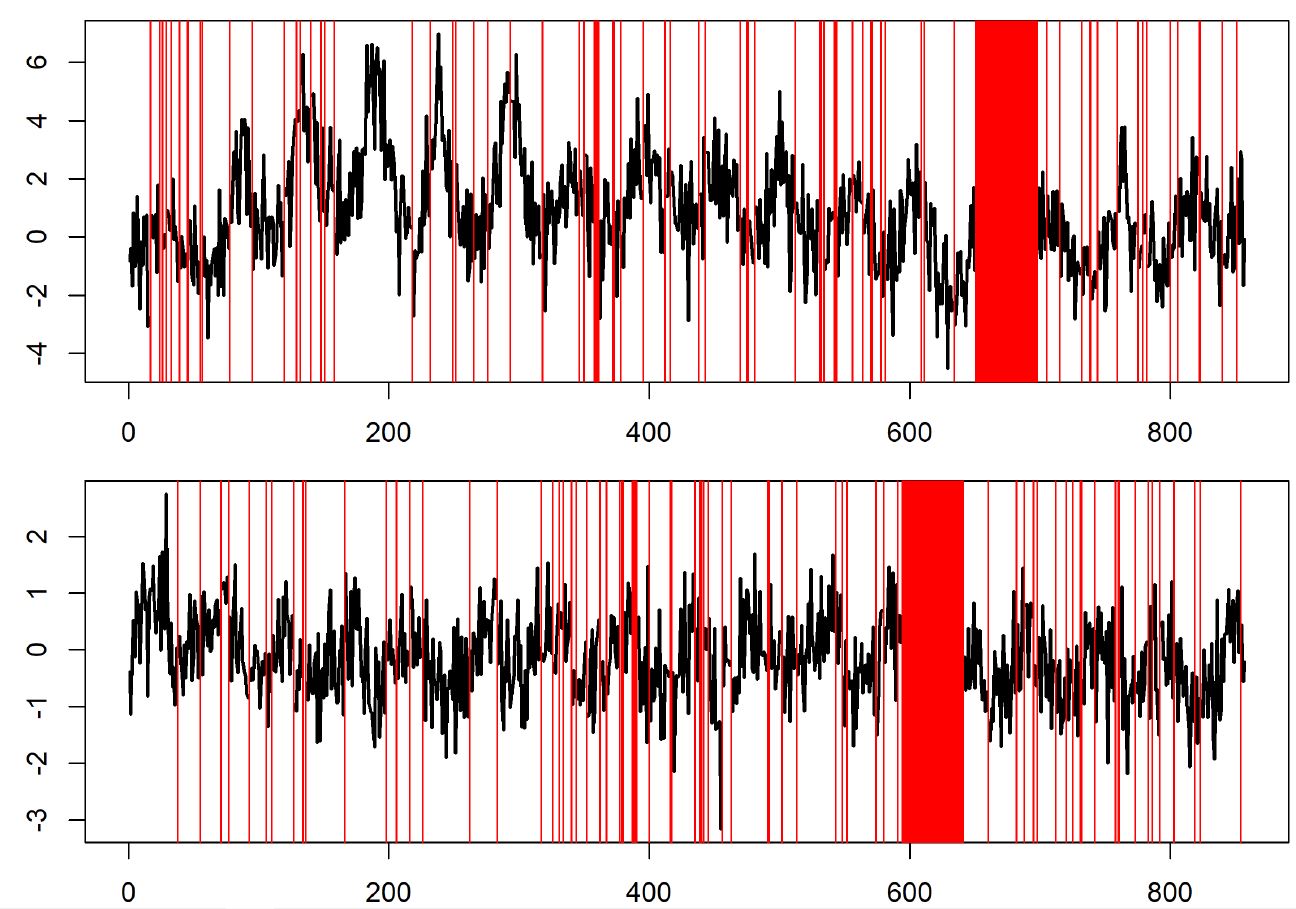
<p>The data were first logged transformed due to their highly positively skewed nature. Second, a dynamic linear model was fit to the data. To capture long-term trend and seasonal behavior, the latent state contained a dynamic intercept and fourier form seasonal components. The models were fit with different levels of fixed discount factors. The posteior mean of \(V\) and \(W_t\) was calculated. New data series were generated from each model fit, with known parameterization. In each copy of the simulated series, missingness was randomly introduced with a frequency distribution matching the original data.</p>

<p><img src="/assets/images/Post_Images/Imputation_simulated_data.JPG" alt="Simulated data" /></p>

<h2 id="analysis--results">Analysis &amp; Results:</h2>

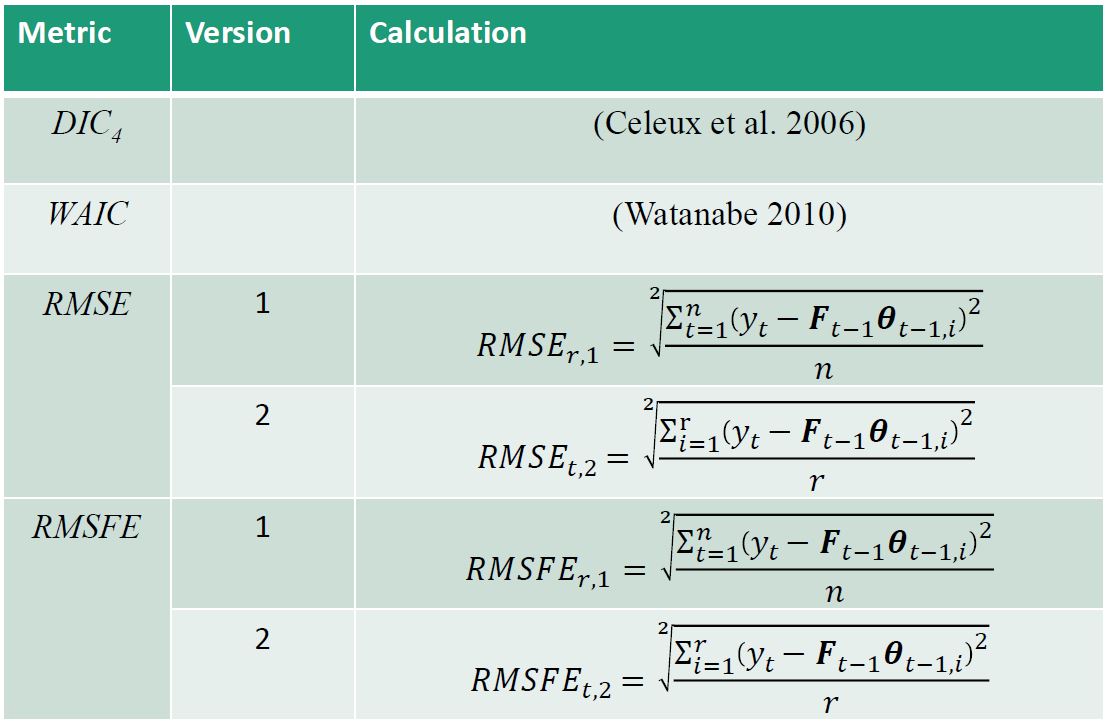
<p>With the simulated data, DLMs were fit with different discount factor levels. The idea is to see if we can recover the discount factors of the data generation model, and which performance criteria helps us make this recovery with the highest accuracy and statistical power. Six performance metrics were calculated and compared to identify which most strongly identified the correct data generation structure.</p>

<p><img src="/assets/images/Post_Images/Imputation_performance_metrics.JPG" alt="performance metrics" /></p>

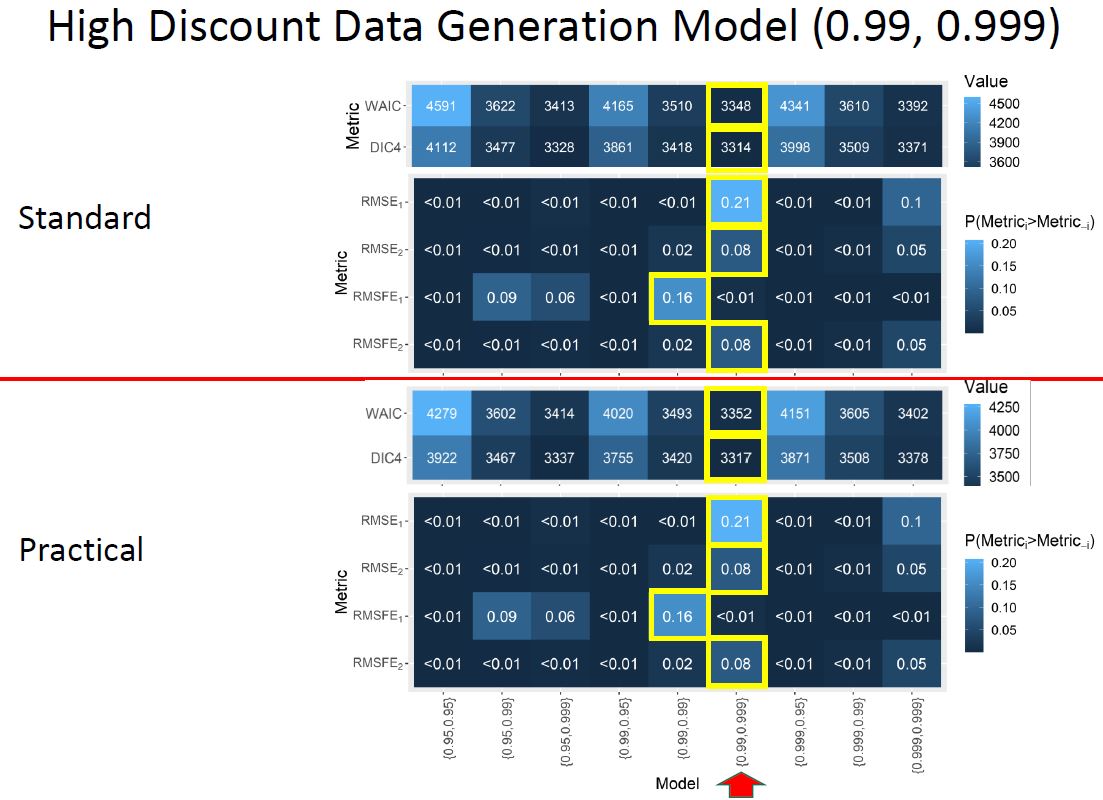
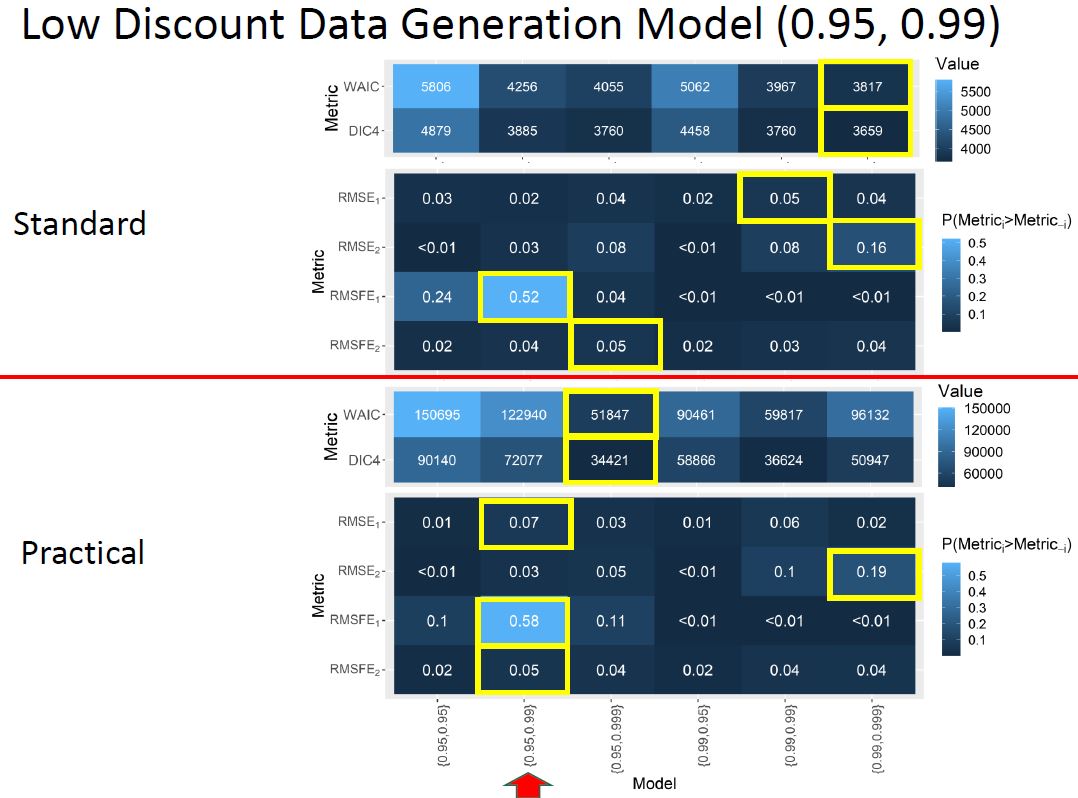
<p>Performance metrics were compared between fits with practical and standard discounting.</p>

<p>For the data generation model of high discount factors our performance metrics are the following for each model fit, where the x-axis is a set of discount factors used in a model fit:</p>

<p><img src="/assets/images/Post_Images/Imputation_highdfgen.JPG" alt="metric compare high df" /></p>

<p>For the data generation model of low discount factors our performance metrics are the following for each model fit, where the x-axis is a set of discount factors used in a model fit:</p>

<p><img src="/assets/images/Post_Images/Imputation_lowdfgen.JPG" alt="metric compare low df" /></p>

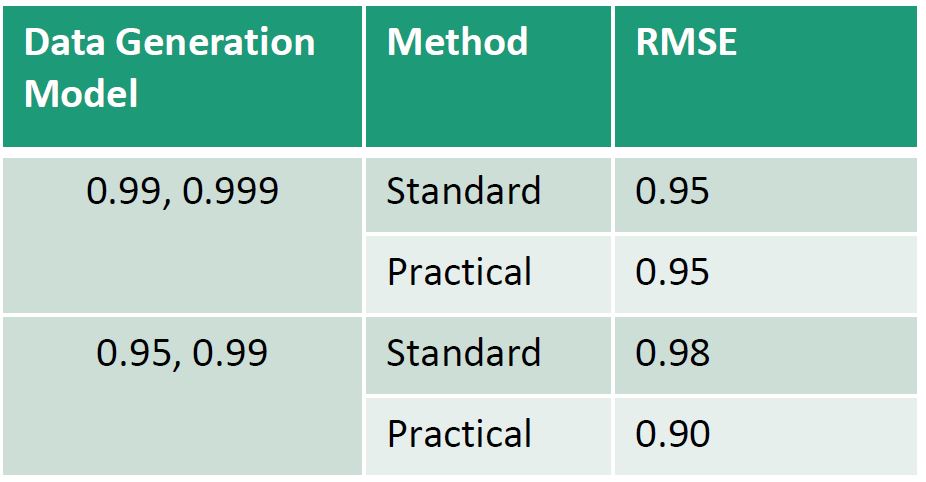
<p>Comparing the standard and practical discounting methods we find the following for each data generation model:</p>

<p><img src="/assets/images/Post_Images/Imputation_accuracyimputationtable.JPG" alt="df method table" /></p>

<h2 id="conclusions">Conclusions:</h2>

<ul>
  <li>Under data simulated with a pair of high discount factors (0.999, 0.99), all metrics selected within 0.009 of the parameters for data generation</li>
  <li>Consistently, $RMSFE_1$ had the most statistical power to recover the parameterization of the data generation model.</li>
  <li>$RMSE$ suggests practical discounting will optimize performance in long-periods of missingness</li>
  <li>DIC support practical discounting imporves the model fit within sample</li>
  <li>Although $RMSE$ was a biased metric for model selection, particularly during prolonged periods of missingness, it still had utility in evaluating the performance of practical discounting in data with long period missingness.</li>
  <li>While $RMSFE$ may be the optimal method for discount factor selection, it does not account for performance during longperiod missingness as our metric of RMSE
does. Therefore, results of RMSE in comparable models with practical and
standard discounting provide an evaluation for this imputation method.</li>
</ul>

<h2 id="literature-cited">Literature Cited:</h2>

<p>Kalman, R. E. 1960. “A New Approach to Linear Filtering and Prediction Problems.” Journal of Fluids Engineering, Transactions of the ASME 82 (1): 35 45. https://doi.org/10.1115/1.3662552.</p>

<p>West, Mike, and Jeff Harrison. 1997. Bayesian Forecasting and Dynamic Models . 2nd ed. Verlag New York: Springer. https://doi.org/10.1007/b98971.</p>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[Time series analysis is the topic that has gripped me since I started studying statistics. Who doesn’t want to better understand the past and predict the future? Most of the data that is collected has a time component which is non-negligable. While some consider the non-independence of data a nuissance for statistical analysis, I consider it one of the greatest opportunities to understand the time pattern.]]></summary></entry><entry><title type="html">Mathematical models of microbial growth</title><link href="https://jacobstrock.com/2022/07/24/Mathematical-Models-of-Microbial-Growth.html" rel="alternate" type="text/html" title="Mathematical models of microbial growth" /><published>2022-07-24T00:00:00+00:00</published><updated>2022-07-24T00:00:00+00:00</updated><id>https://jacobstrock.com/2022/07/24/Mathematical%20Models%20of%20Microbial%20Growth</id><content type="html" xml:base="https://jacobstrock.com/2022/07/24/Mathematical-Models-of-Microbial-Growth.html"><![CDATA[<p><img src="/assets/images/Post_Images/darwin_model.jpg" alt="darwin model globe" /></p>

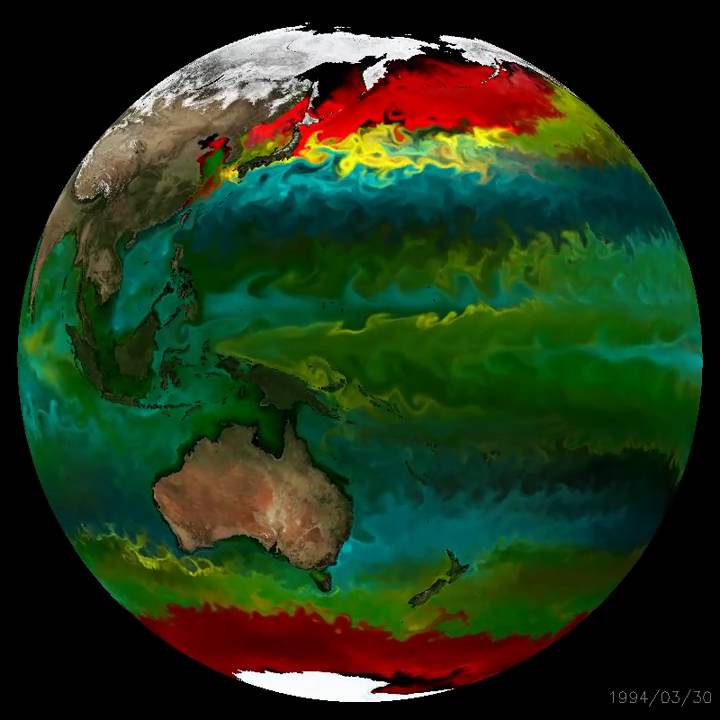
<p>Marine microbes are some of the most numerous organisms in the world. Although you may have never seen or though about them, they make our planet survivable in many ways (not the least of which is producing 50% of the atmospheric oxygen we breathe and forming the base of the food we in all the world’s oceans). Despite being so numerous and critical to life on our planet, there are major gaps in our understanding of how these tiny organisms are shaped by their environment.</p>

<p>Under a fellowship with NASA Space Grant, I studied how temperature impacts these critical organisms. In this project, by creating mathematical models of microbial growth and size as a function of temperatures, I provided a small piece of NASA’s large numerical models that work to model and predict our own planetary function.</p>

<p>If you would like the full details of the published study, you can read it here:</p>

<object data="/assets/supplementaryfiles/Strock__Menden-Deuer_LO2020.pdf" width="1000" height="1000" type="application/pdf"></object>

<h3 id="objective">Objective:</h3>

<p>Measure the growth and cellular size traits of a globally relevant marine algae.</p>

<p>Mathematically model how the cellular traits are impacted by temperature. Use interpretable statistical models that can be used for prediction and ecological interpretation. From the start, we had several targeted questions:</p>

<ol>
  <li>How do populations of microbes grow across a wide range in temperatures?</li>
  <li>How are the sizes of the microbial cells impacted across a wide range in temperature?</li>
  <li>How much do changes in temperature (thermal perturbations) impact population growth?
    <ul>
      <li>Does the impact from change itself impact our ability to estimate temperature effects?</li>
    </ul>
  </li>
</ol>

<p>Use ocean thermal data and mathematical models of thermal responses to estimate the magnitude of thermal effects on microbial function.</p>

<h3 id="data">Data:</h3>

<p><strong>Cells and Culture Growth</strong></p>

<p>As a study case for the biological response of algae to temperature and temperature change, I chose an algae which is both common and toxic, <em>Heterosigma akashiwo</em>. The cells  were kept healthy, in exponential growth. To avoid convolution of the thermal response with
the response to new media, cultures were only transferred to
new media more than 1 d prior to and 1 d post to a change in
temperature.</p>

<p><strong>Temperature treatments</strong></p>

<p>With little prior information as to which features of changing
temperature might influence growth, two major traits were
examined in the experimental design: (1) the direction of temperature
change (increasing or decreasing) and (2) the magnitude
of temperature change (small shifts vs. larger cumulative
changes). To address these features, and represent realistic
rates of change, cultures were shifted sequentially to new
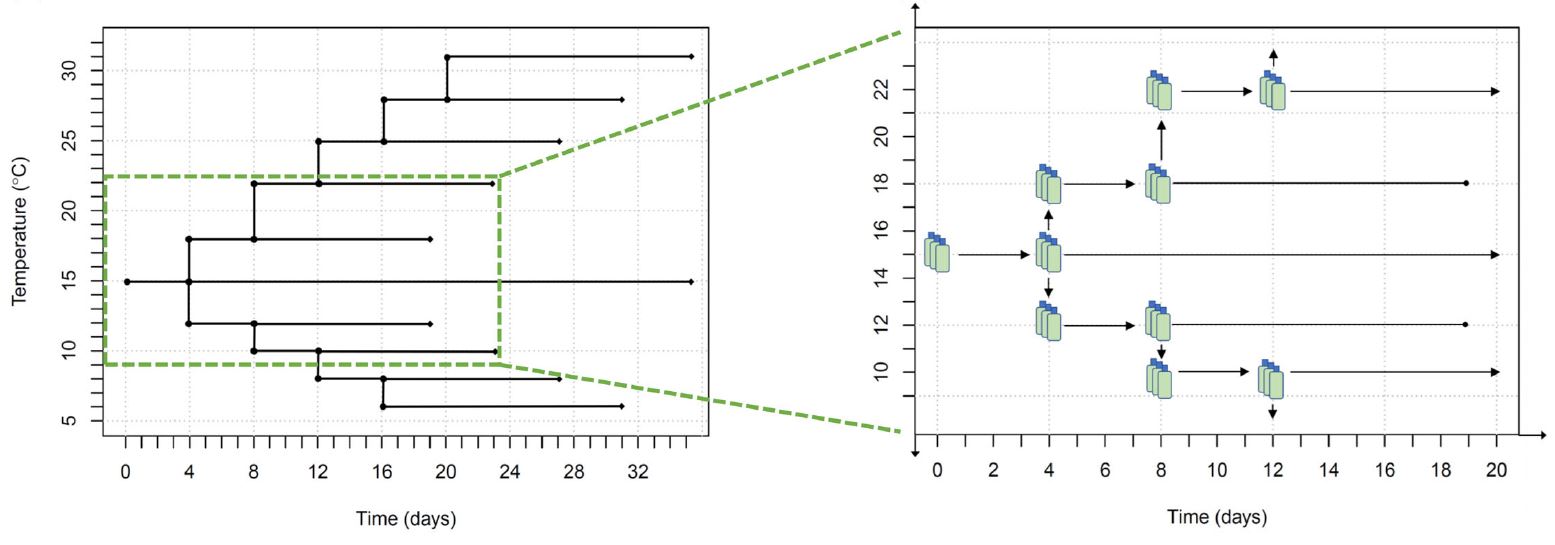
growth temperatures outward from 15\(^{\circ}\)C (Fig. 1). Including
the control culture, growth rate, and acclimation was measured
at 10 temperatures: 6\(^{\circ}\)C, 8\(^{\circ}\)C, 10\(^{\circ}\)C, 12\(^{\circ}\)C, 15\(^{\circ}\)C, 18\(^{\circ}\)C,
22\(^{\circ}\)C, 25\(^{\circ}\)C, 28\(^{\circ}\)C, and 31\(^{\circ}\)C. As each incubator had a static
temperature, we used small discrete shifts in temperature over
time. Beginning with the culture that was acclimated to 15\(^{\circ}\)C,
every 4 d a triplicate set of the cultures growing at the highest
and lowest current temperatures were split, with one fraction
retained at its current temperature and the other fraction
shifted one temperature step outward (i.e., further toward the
temperature extremes of 6\(^{\circ}\)C and 31\(^{\circ}\)C.</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure1.JPG" alt="figure 1" />
<strong>Figure 1</strong>: <em>Experimental temperature treatement design and temporal component to data collection.</em></p>

<p><strong>Data Collection</strong></p>

<p>To quantify changes in cell size, population growth rate
(cell numbers), and volumetric growth rate, the abundance
and cell size distribution were measured with a Beckman Coulter Multisizer 3 for 15 d following the initial transfer to the target temperature.</p>

<h3 id="data-processing">Data Processing:</h3>

<p>The measurement taken in this study, for which, all statistics are derived are cell size distributions. The Coulter counter is a machine which counts the number of particles in size bins from ~1 to 100 \(\mu\)m. Measuring the number of cells in culture with automated instruments, can be produce suprisingly noisy data that need to be cleaned. Particularly, decaying material and undesireable cell populations in the culture may show signals in the data.</p>

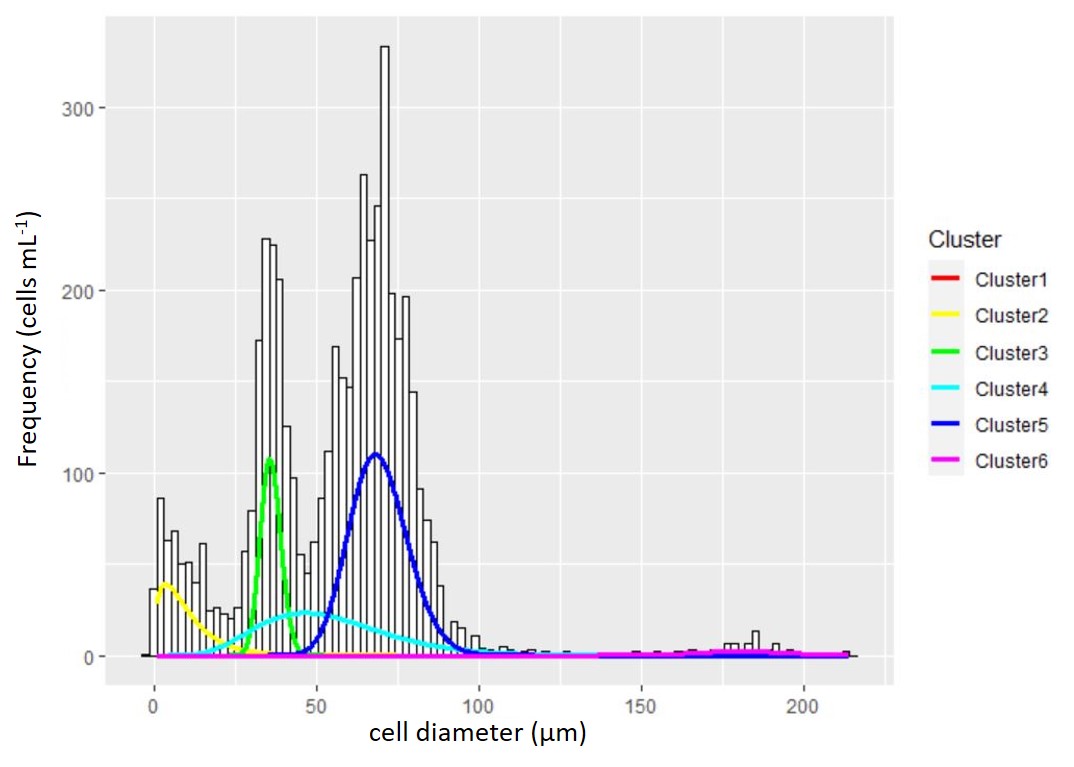
<p>While normally the data are processed by hand, I automated the processing of thousands of cell distributions by fitting a mixture of a Gaussian and exponential mixuture model to the cell size distribution data, I quantified the mean and variance of the size distribution and number of cells in the target population. The traits of these population measures served as the key independent varaibles in the desired mathematical models of growth. Below you can see an example of a cell size distribution with overlaid Gaussian density curves:</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure2v2.jpg" alt="figure 2" />
<strong>Figure 2</strong> : <em>A particle and cell size distribution is fit with a mixture of distributions to identify the true cell count and population characteristics. The raw data collected from the Coulter counter is the underlying histogram of cell size with frequency on the y-axis and cell size on the x-axis. To fit the mixture distribution, the frequency data is first converted to raw measurements of individual cells. The density distributions from the mixture model are overlaid for graphical reference to the model fit. Unlike most clustering cases where the true number of clusters cannot be known, microscopy was used to verify the number of true cell populations and possibly multiple cell size groups of the same population.</em></p>

<p>Population growth rates were calculated by fitting an exponential growth curve to the population data:</p>

\[P_t = P_0 * e^{rt}\]

<p><em>where:</em></p>

<ul>
  <li>\(P_t\) is the population at time \(t\)</li>
  <li>\(P_0\) is the original population</li>
  <li>\(r\) is the growth rate</li>
  <li>\(t\) is the elapsed time</li>
</ul>

<h3 id="analysis--results">Analysis &amp; Results:</h3>

<p><strong>1.) How does temperature affect growth rate?</strong></p>

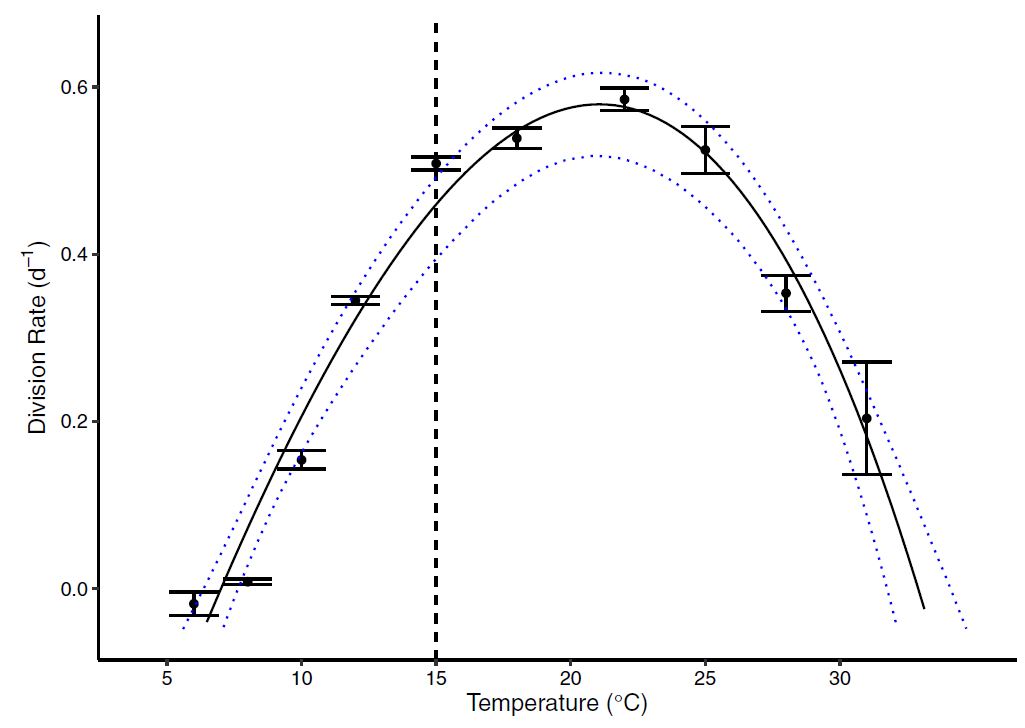
<p>With maximum likelihood estimation, I used the calculated specific growth rates were to fit a standard thermal reaction curve used in biology:</p>

\[k(T) = a*e^{bT}[1 - (\frac{T-z}{w/2})^2]\]

<p><em>where :</em></p>

<ul>
  <li><em>a, b, and z are shape parameters</em></li>
  <li><em>w is the thermal niche width</em></li>
  <li><em>T is a given temperature</em></li>
  <li><em>k(T) is the specific growth rate at that temperature</em></li>
</ul>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure3.JPG" alt="Figure3" />
<strong>Figure 3</strong> : <em>The thermal reaction norm showed a clear thermal dependence with a tolerable range (\(w = 25.9^{\circ}\)) spanning from \(7^{\circ}C\) to \(33^{\circ}\). This upper temperature range suggests that the marine algae can survive to some of the hottest temperatures seen in the ocean, and are likely to tolerate further warming with continued positive growth rates. However, warming beyond the optima (\(z=20^{\circ}C\)) will result in thermal stress.</em></p>

<p><strong>2.) How are the sizes of cells impacted by temperature?</strong></p>

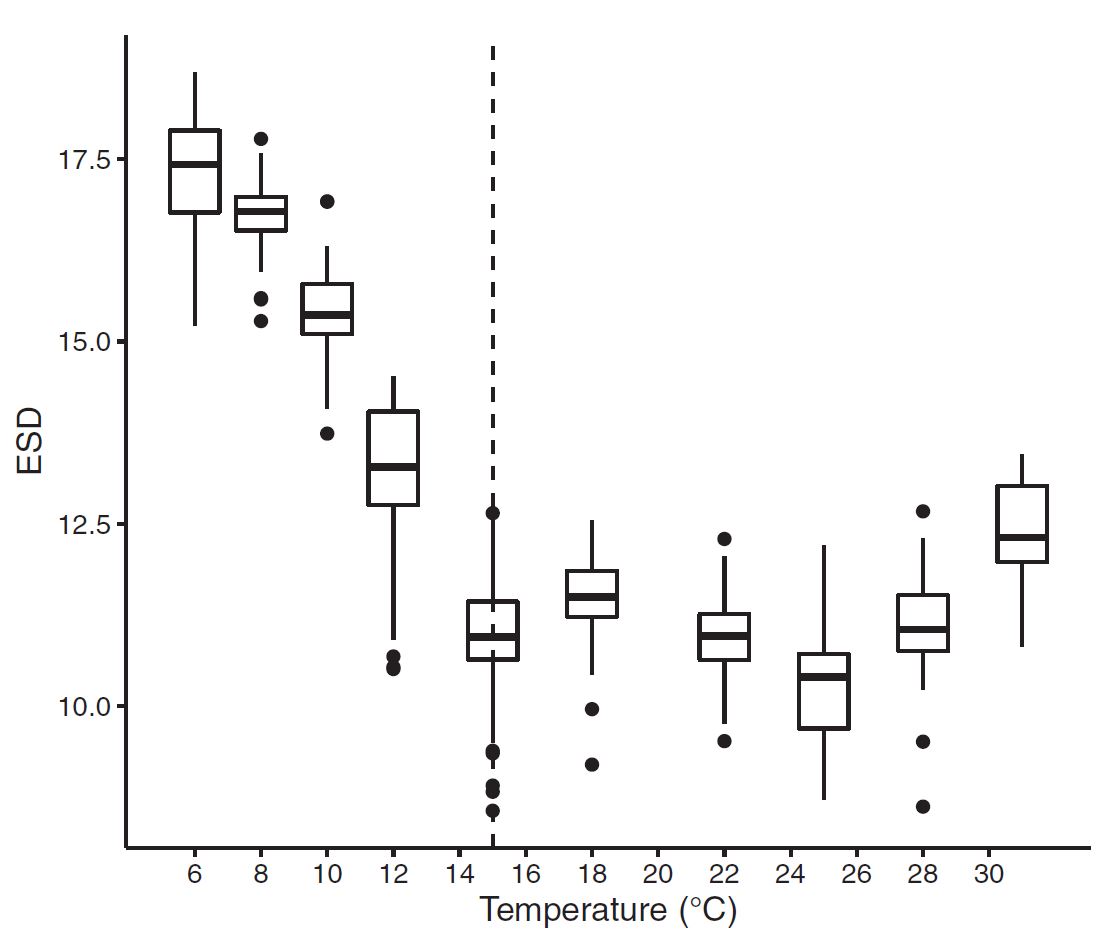
<p>And analysis of cell size showed that both the devision rate and cell size were closely tied to temperature:</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure6.JPG" alt="Figure6" />
<strong>Figure 4</strong>: <em>ESD (Cell diameter) measurements across temperature. Results show a clear relationship with generally decreasing cell size as temperature increases.</em></p>

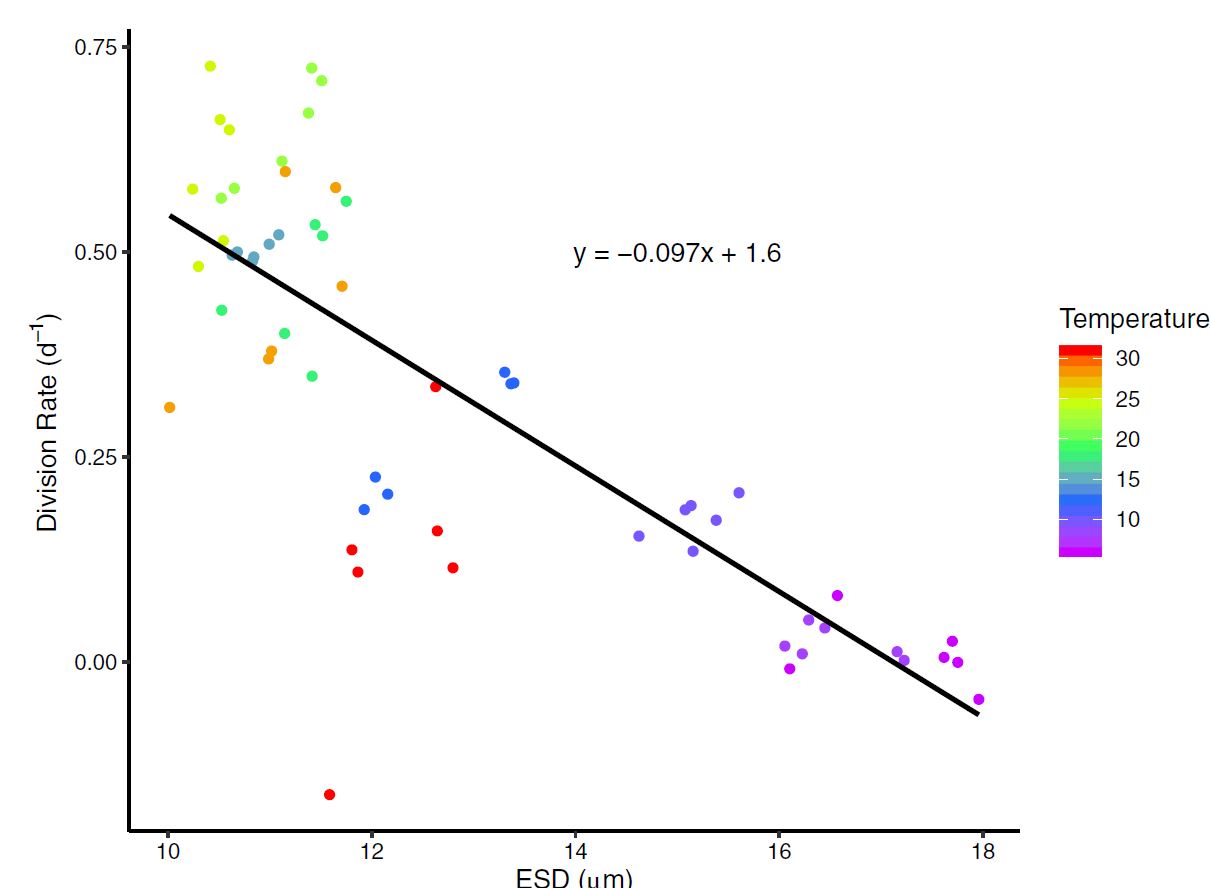
<p>While the relationship between cell size and temperature is strong, nuance here is important. From the graphical outputs, I had noted, the cell size relationships and aberations from linearity seemed to match an inverse of the temperature growth curve. After noting some-nonlinearity in the relationship, and conducting other exploratory comparisons, I tested whether there was another explainatory reason for cell size changes.</p>

<p>After comparing multiple models (AIC) with a type II regression, I showed that cell size was best explained by cell division rates. This is important to our understanding because the evidence suggests that it’s not temperature directly, and potentially any influences on division rates will affect cell size.</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure5.JPG" alt="Figure5" />
<strong>Figure 5</strong> : <em>A type II regression fit between ESD (cell size) and division Rate (population growth rate). The temperature treatement where each measurement was recorded is shown in color.</em></p>

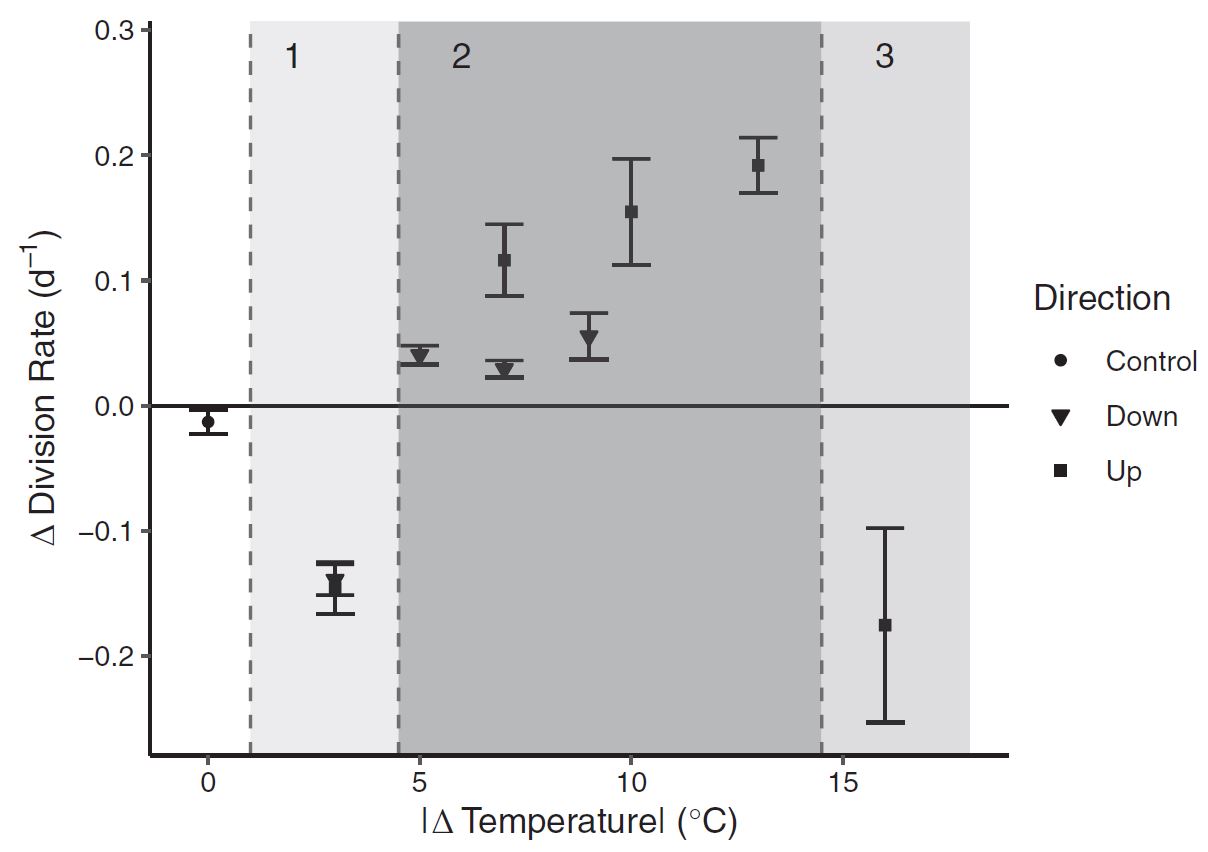
<p><strong>3.) How much does change itself impact population growth and cell size?</strong></p>

<p>To quantify the effect of time (acclimation) on specific
growth rate, the final rates (\(\mu_f\), 7 ≤ \(\Delta\) time ≤ 15 d) were subtracted
from the initial rates, measured over the first 3 d (\(\mu_0\);
\(\Delta\) time ≤ 3 d) for each temperature treatment.</p>

<p>A break-point detection and Dunnet’s test showed three distinct response groups: 1.) Small thermal changes which lowered growth rate immediately 2.) Medium changes which accelerated growth 3.) Extreme changes which again lowered growth. To be brief, there are biological mechanisms we hypothesize which can explain these patterns, but further detailed molecular metabolic research would be needed to understand these response patterns fully. Nonetheless, we have evidence that changing temperature dramatically effects growth rates.</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure7.JPG" alt="Figure7" />
<strong>Figure 6</strong>: <em>Growth rates were dramatically impacted by the cumulative magnitude of temperature change itself.</em></p>

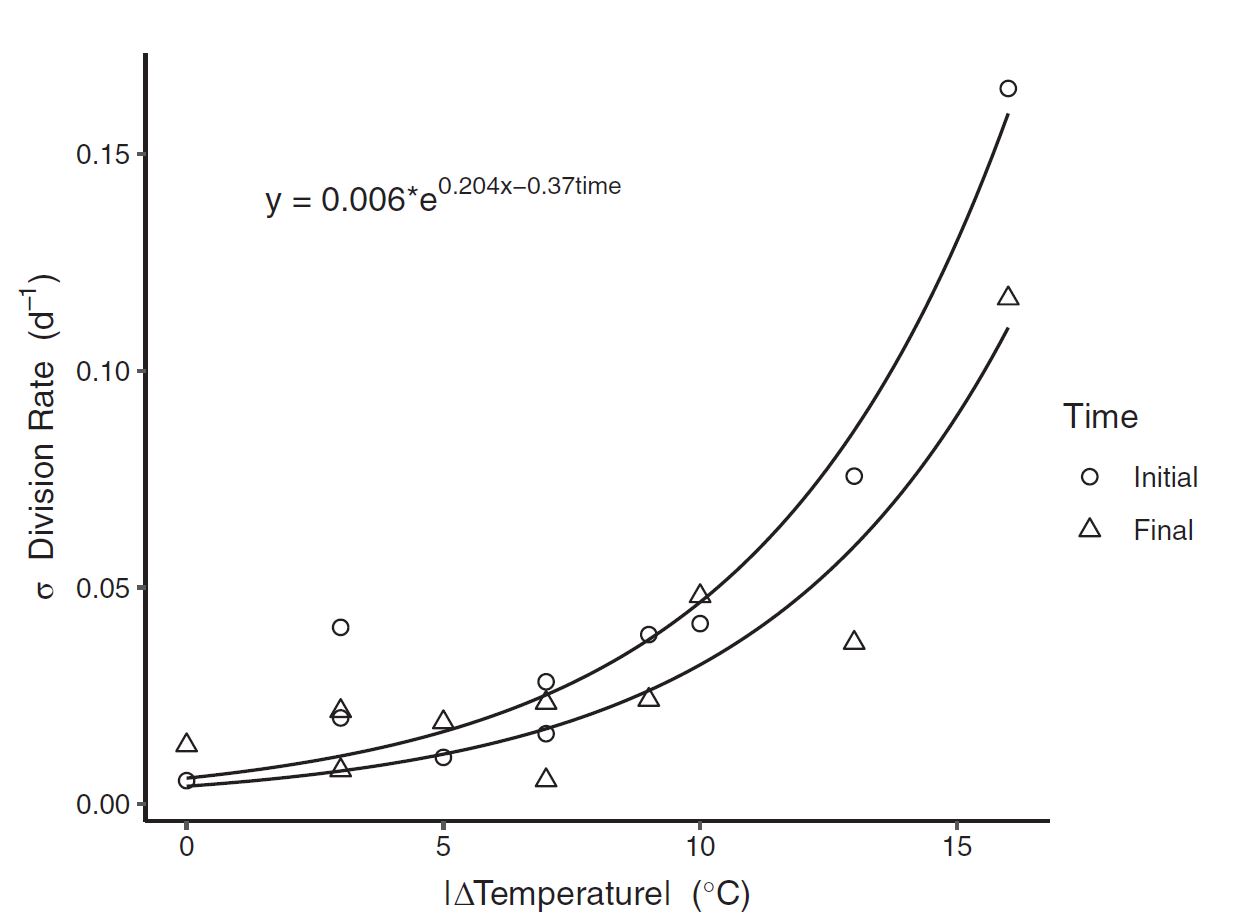
<p>Last, to understand patterns in the variability of growth rate among replicates as a
function of the cumulative temperature change
(\(\Delta\)Temperature) and time (translated into a binary variable; \(t_0\)
and \(t_f\) to 0 and 1, respectively). After graphically examining the variance in growth rate relative to temperature changes, an exponential relationship
was fit to the SD of the specific growth rate (σ). The following regression was again fit with maximum likelihood expectation (MLE):</p>

\[\sigma = c * e^{d*\vert\Delta T\vert - e*time}\]

<p><em>where:</em></p>
<ul>
  <li><em>c, d, and e are shape coefficients</em></li>
  <li>\(\sigma\) <em>is the specific growth rate</em></li>
  <li><em>T is a given temperature</em></li>
  <li><em>t is the time after temperature change</em></li>
</ul>

<p>Temperature change caused an exponential level increase in biological variability. And the power of the exponent decreased with time. This may seem esoteric, but the fundamental origins of biolocal variability are an open ended question in biology, and any evidence that can explain why organisms vary is valuable. Here our data evidences how environmental peturbations can rapidly diversify a population.</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure4.JPG" alt="Figure4" />
<strong>Figure 7</strong>: <em>Standard deviation in division rate (between replicates) as a function of the magnitude of temperature change. The exponential fit suggests that biological variablity increases exponentially as a result of environmental variation.</em></p>

<p><strong>How much can thermal variability impact estimates from a standard thermal performance curve?</strong></p>

<p>To exemplify, the impact of the thermal response on microbial growth as well as the potential magnitude of new-found acclimation effects, I extracted seasonal data from varied oceanographic sites within the thermal range of our study organisms. By imputting, this data into the fitted thermal performance curve we made a prediction on population growth and production.</p>

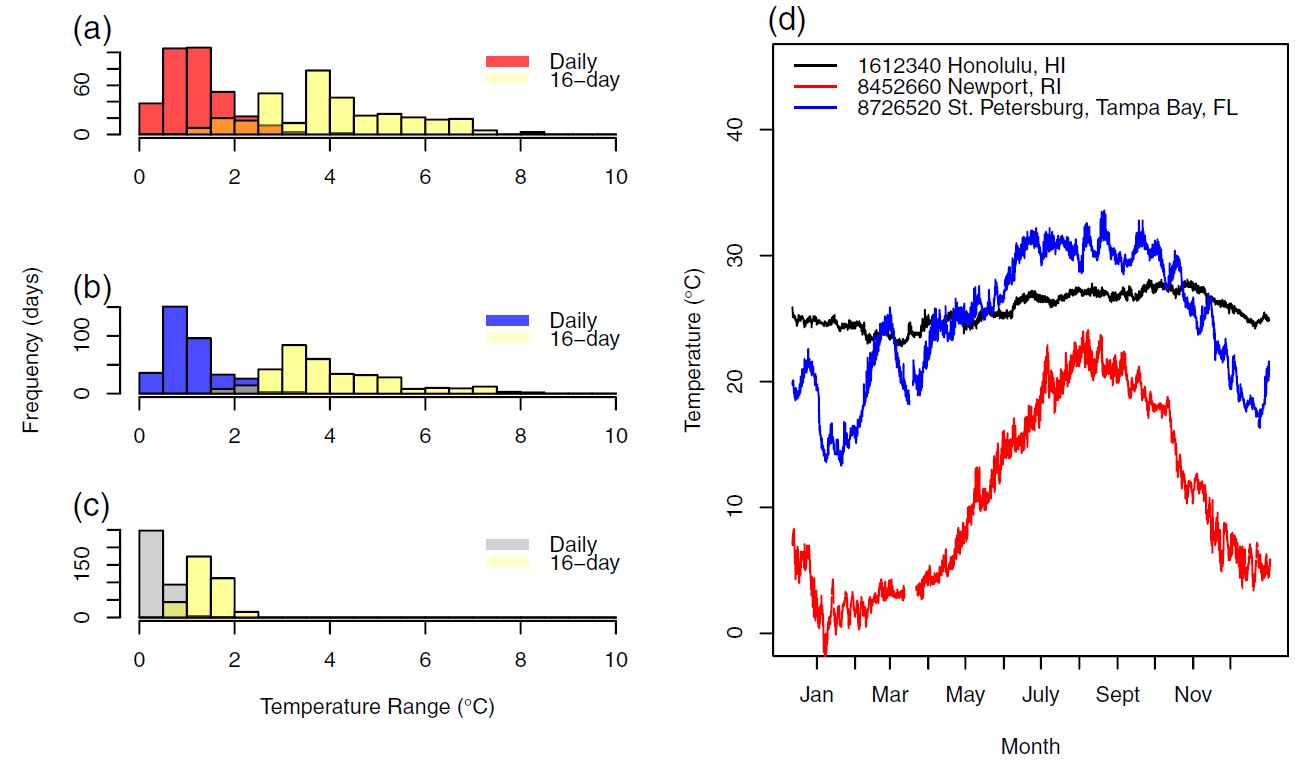
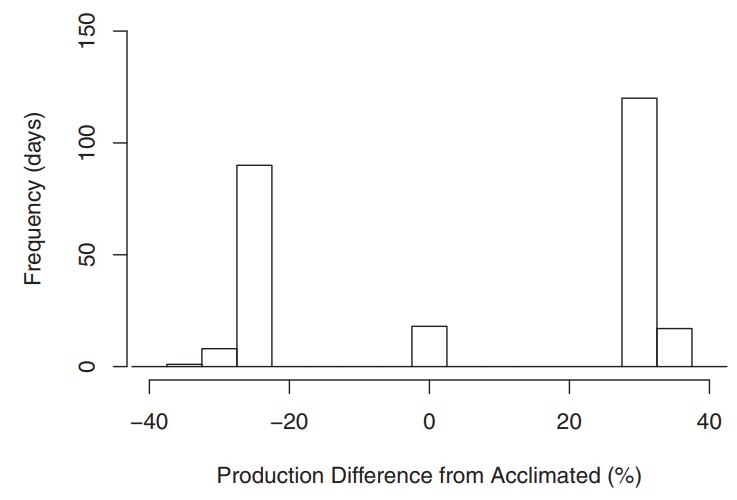
<p>Collecting enough laboratory data to fit any complex function or non-parameteric model to the acclimation data was impossible. As you can see from the raw data of figure 6 above, limited sample size limits the modeling options. Nevertheless, we would be remiss not to make an estimate of potential effects. Using a moving window to quantify the total temperature change an organism would experience, a scaling factor was used based on the response shown in figure 6. Consistent with the results where different magnitudes of temperature change elicited different acclimation responses, we applied a correction equal to the difference in initial and final growth rates observed at each magnitude in temperature change. Specifically, three temperature ranges in the thermal history window elicited different responses: \(3–5^{\circ}C\), \(5–13^{\circ}C\), or greater than \(13^{\circ}C\) (see “Results” section). The average specific growth rate difference (i.e., acclimation) for these three thermal ranges were −0.14 \(d^{−1}\), 0.10 \(d^{−1}\), and −0.18 \(d^{−1}\), respectively. These differences were added to the acclimated rate interpolated from the thermal performance curve. That is, when the thermal history window had a temperature range of \(3–5^{\circ}C\), \(5–13^{\circ}C\), or greater than \(13^{\circ}C\), a −0.14, 0.10, or −0.18 \(d^{−1}\) correction was added to the growth rate inferred from the thermal performance curve. Cases where no growth was observed wereomitted. The percent difference between final and initial growth responses were compared for each day.</p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure8.JPG" alt="Figure8" />
<strong>Figure 7</strong>: <em>With real-world data used for simulation, within the habitat of our target organism, temperature frequently varied to levels where we had seen measureable response to the variability itself.</em></p>

<p><img src="/assets/images/Post_Images/MicrobialGrowthModels/Figure9.JPG" alt="Figure9" />
<strong>Figure 8</strong>: <em>Comparing cases to when acclimation was and wasn’t accounted for, there was potential for major discrepencies in growth estimates. The x-axis shows the magnitude of population growth differences in percent. The y-axis shows the number of days (out of 1 year) falling in each histogram bin. This results suggest that in any environment with high seasonality, further research to quantify variabilty responses will be necessary for accurate estimations.</em></p>

<h3 id="conclusions">Conclusions:</h3>

<ul>
  <li>Marine algae are highly dependent both on the magnitude of temperature, as well as thermal fluctuations</li>
  <li>Cell  size of microbial organisms carry a clear linear relationship to division rate, and consequently may appear to vary with temperature.</li>
  <li>This toxic algae can handle a wide range in temperatures, and in many habitats may see continued increase in growth as the planet warms</li>
  <li>Biological variability intensifies exponentially as the environment changes (as seen through thermal shifts)</li>
  <li>Acclimation responses can impact estimates of biological production 36% under ordinary seasonal thermal conditions.</li>
</ul>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Nonporportional hazards models for patient outcomes</title><link href="https://jacobstrock.com/2022/07/09/Nonporportional-Hazards-Models-for-Patient-Outcomes.html" rel="alternate" type="text/html" title="Nonporportional hazards models for patient outcomes" /><published>2022-07-09T00:00:00+00:00</published><updated>2022-07-09T00:00:00+00:00</updated><id>https://jacobstrock.com/2022/07/09/Nonporportional%20Hazards%20Models%20for%20Patient%20Outcomes</id><content type="html" xml:base="https://jacobstrock.com/2022/07/09/Nonporportional-Hazards-Models-for-Patient-Outcomes.html"><![CDATA[<p><img src="/assets/images/Post_Images/nonproportional_hazards.jpeg" alt="nonproportional hazards" /></p>

<p>During the COVID-19 pandemic, I had the privelage to work on the Northeast Big Data Innovation Hub project <a href="https://nebigdatahub.org/critcovidview/"><em>CritCOVIDView: A Critical Care Visualization Tool for COVID-19</em></a>. Led with the clinical and research expertise of Todd Brothers PhD, PharmD and Mohammad Al-Mamun PhD, as part of the team, I created data processing pipelines, conducted statistical analysis for insight and trained statistical models for predicting patient outcome and the clinical influences on these outcomes. The core goal of this project was to develop predictive models and statistical insights to help clinicians make data driven medical decisions during the COVID crisis with the insights and analysis from high dimensional patient data. Recently,  some of the survival (aka time to event) modeling work was published in the medical journal <a href="https://journals.sagepub.com/doi/10.1177/20503121221099359">SAGE open Medicine</a>.  In this post, I will summarize the modeling components of this paper that I worked on as part of the team.</p>

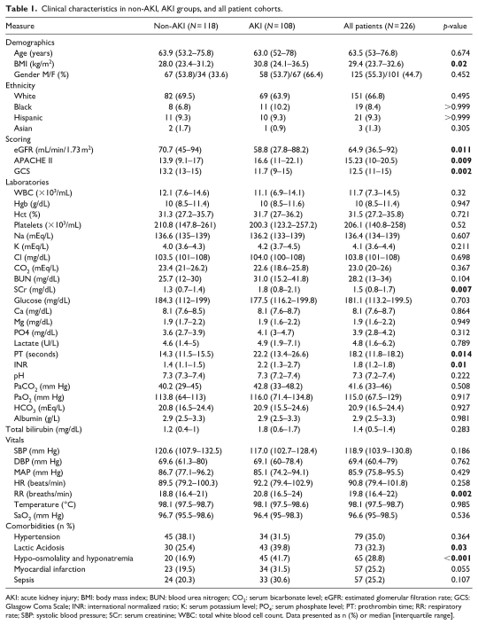
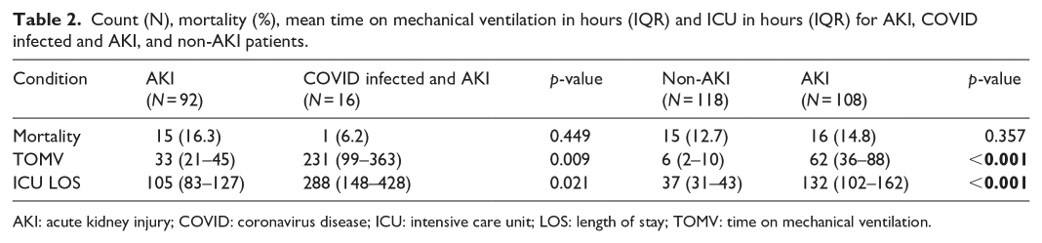
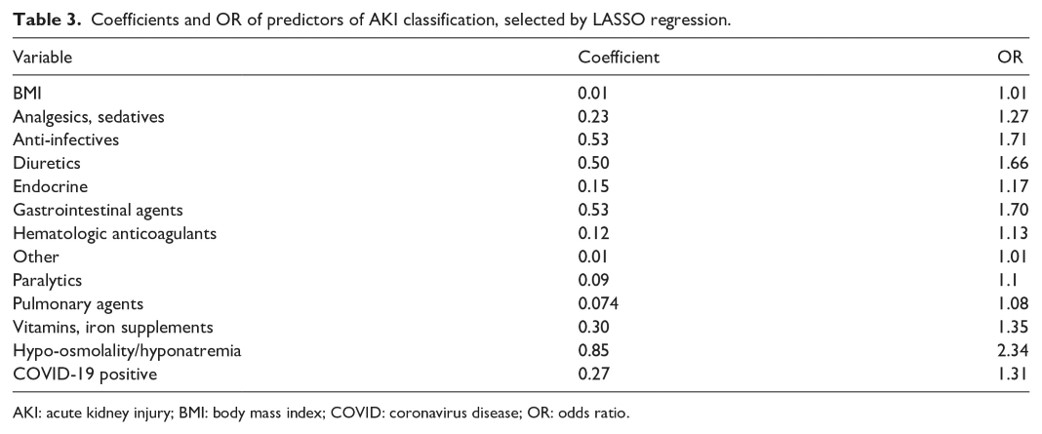
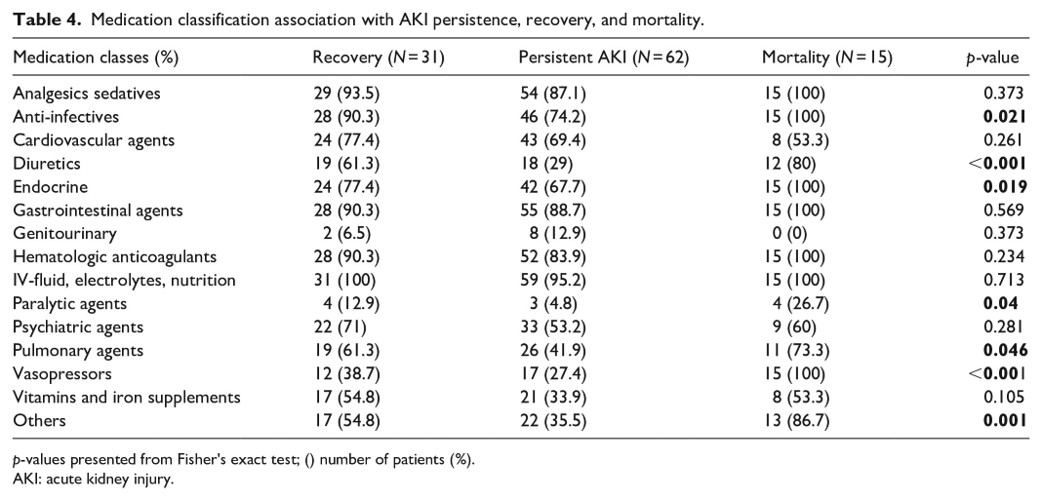
<p>This project  targets analysis of the interaction between the prevalent and dangerous condition of Acute Kidney Injury (AKI), and the interaction with medications, patient demographics, and COVID infection.</p>

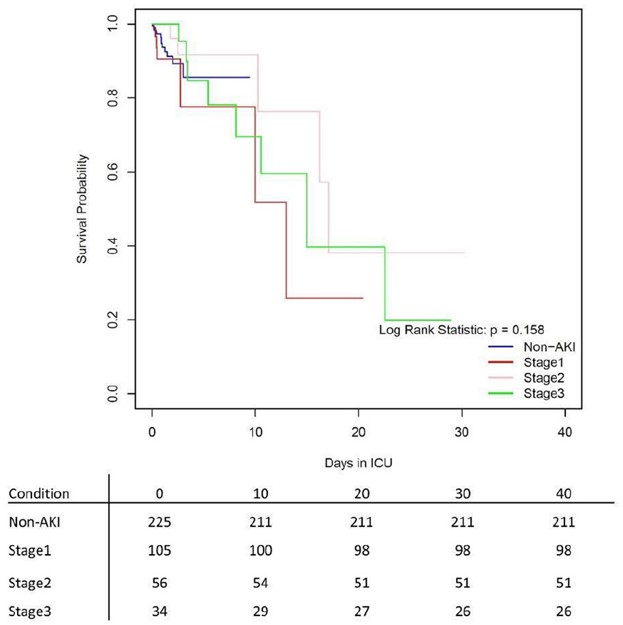
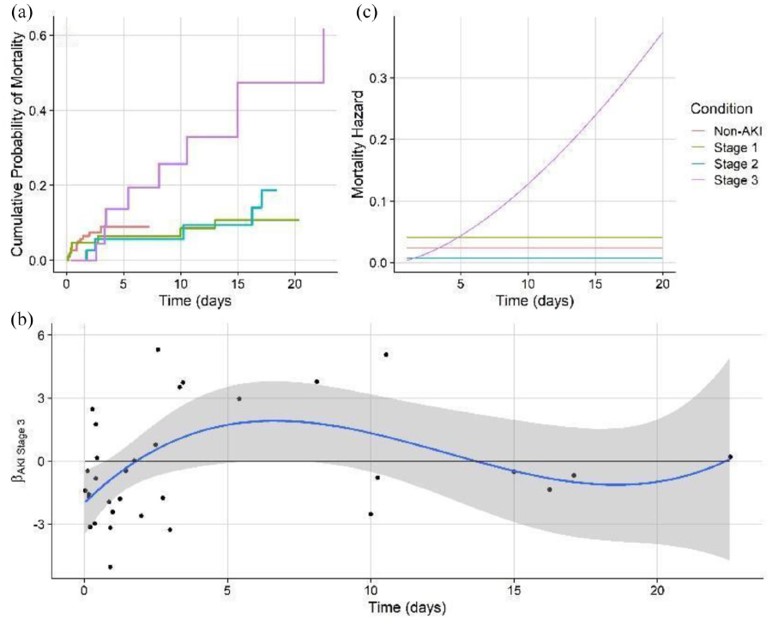
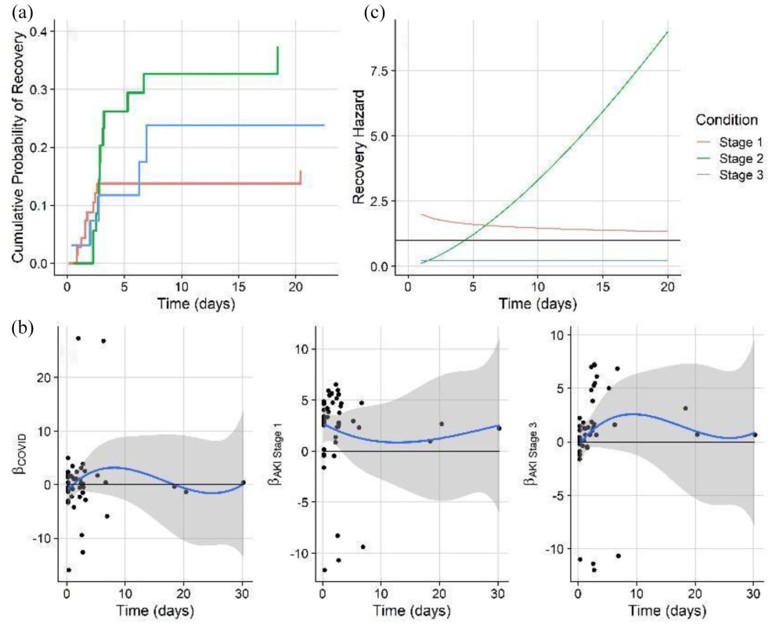
<p>Because of the sensitivity of the data I can neither share the data nor analysis code, but I can and will provide a description of the analysis process, results, and implications.</p>

<object data="/assets/supplementaryfiles/AKI_Survival_Recovery.pdf" width="1000" height="1000" type="application/pdf"></object>

<h2 id="objective">Objective:</h2>

<p>Acute Kidney Injury (AKI) is a dangerous condition and unfortunately common condition in the ICU, impacting millions of patients every year and associated with a wide range in adverse patient outcomes including death. The goal of this analysis is to model the outcomes of these patients (both mortality and recovery) as well as to identify the treatment and patient conditions that may impact the patient outcome.</p>

<h2 id="data">Data:</h2>
<p>This study recieved all proper ethical approval (see publication details), and used deidentified, retrospective data.</p>

<p>226 ICU patients were included in this study. Data included all available records of vitals, demographics, medications recieved, laboratory readings (from blood-work), and oxygenation. All patient data were available in completion during the entirety of the patient stay.</p>

<h2 id="data-processing">Data Processing:</h2>
<p>AKI as a condition can be classified into 3 stages (stage 3 being the most severe), and was calculated via the criteria of the Kidney Disease Improving Global Outcomes standard. To accomplish this, I created a data pipeline which used rolling windows, applied over the temporally structured data, to detect the AKI criteria during the patient staty. By applying the AKI criteria in rolling windows of the patient data, important temporal traits were retained such as the time to onset of AKI, worsening/improving of condition over time, and time between diagnose and outcome (recovery/mortality).</p>

<p><img src="/assets/images/Post_Images/patients_included_KDIGO.PNG" alt="Patient Classification" /></p>

<p>First, the descriptive statistics were calculated for each study group. The mean and interquantile range were calculated for each continuous variable, and for categorical variables, the count and percentage of patients meeting the conditon were calculated. To statistically test differences between the study groups, pair-wise t-tests were used for continous varaibles, and a chi-square test was used for categorical features. Fisher’s exact test was used to statistically test differences in count data for medications classes received due to the small sample sizes for patients recieiving certain medication categories.</p>

<p>To prepare the data for survival modeling, the data had to be processed into a time-to-event format. In this format, each row was occupied by the data for a given patient and condition status. In example, it may designate the AKI stage 1 status of patient X. If patient X was also non-AKI, a seperate row would designate their data for the non-AKI period of their stay. Each row contained an event (recovery, worsening AKI condition, mortality), the time from diagnosis or ICU entry to the event, the patient demographics, and average laboratory, oxygen, and vitals data. In addition, a dummy encoding was used for the medication classes received during their stay. Altogether, the transformed data gave information on the time to event, the event, and the patient conditions leading up to the event.</p>

<h2 id="analysis--results">Analysis &amp; Results:</h2>

<p>The first basic question is how our AKI vs non-AKI patients compare. A descriptive table and pairwise comparisons (chi-square and t-test for categorical and continous variables respectively) were used to describe the differences between the cohort of AKI and non-AKI patients.</p>

<p><img src="/assets/images/Post_Images/Table1.jpg" alt="Table 1" /></p>

<p>Outcomes included the time in ICU, time on mechanical ventilation, and mortality rates were also compared for each cohort</p>

<p><img src="/assets/images/Post_Images/Table2.jpg" alt="Table 2" /></p>

<p>After establishing medical differences between our AKI and non-AKI patients, we then ask what might predict a patient becoming an AKI patient. AKI classification (binary reponse variable) was predicted in a LASSO logistic model, a model which penalizes parameters, such that the model can serve for feature selection. The features selected by the model provide information on what predicts AKI classification and comparison of the odds ratio between the AKI and non-AKI group inform us to the effect size.</p>

<p><img src="/assets/images/Post_Images/Table3.jpg" alt="Table 3" /></p>

<p>We also asked which medication classes might influence the AKI outcome (recovery, persistence of AKI, or mortality). Because the sample size limited statistical power in survival models, I employed a fisher’s-exact test to compare the number of patients receiving a given medication class, with the patient outcome as a dependent variable. That is the test compared whether more patients with a certain outcome received a given medication category. The Fisher’s exact test was used because of the ability to statistically test small sample sizes.</p>

<p><img src="/assets/images/Post_Images/Table4.jpg" alt="Table 4" /></p>

<p>I calculated the Kaplan-Meier curve, which shows survival probability by each AKI class. It is a standard in survival modeling and we chose to show it as a reference. However, usage of this curve often violates statistical assumptions, and the same is true here (Later we will go on to show with non-proportional hazard modeling how survival differences become apparent with the correct model structure). While Kaplan-Meier estimates of emperical surival probabiltiy show little difference in the survival probablity in any of the AKI groups, it does not account for competing outcomes which means, that multiple events can happen which prevent a patient from experiencing a single target event. For example, in our data, a patient may be diagnosed with AKI stage 1. The event we are monitoring may be recovery, but they may also become censored from the study because they became a more severe AKI stage, or died. Further, the often cited log-rank statistic which test for differences in survival curves by group cannot handle time-varying differences in survival probablity. Clearly, these are major assumptions that must be addressed.</p>

<p><img src="/assets/images/Post_Images/Figure2.jpg" alt="Figure 2" /></p>

<p>As a consequence of the nature of competing hazards in our data, a cox regression was used to test the difference in the proportional hazards for recovery and mortality in each of the AKI classified patient groups and control group. The target variables in independent models were recovery and mortality. The included predictors were AKI status, demographic traits, and medication class received.</p>

<p>The Cox proportional hazards model, is a model for the hazard rate, or the instantaneous probability of an event occuring. Obviously, in the real world, instantaneous rates are difficult to interpret, but if this rate is integrated over time, it gives the probability of an event occuring up to that point in time. Further, the parameterization of the Cox model for the instantaneous hazard will give us valuable information about what influences the probability of an event (like recovery or mortality) occuring. The Cox proportional hazards model is configured as such:</p>

\[\lambda(t \vert X_i) = \lambda_0(t)exp(\beta_1 X_{i1}, + ... + \beta_p X_{i,p})\]

<p>However, analysis of the Schoenfield residuals showed significant time-variation in the covariate effects. 
Therefore, a non-proportional hazards model was run whereby features that signficantly time varied as indicated by Schoenfeld residuals, were given temporal flexibility.</p>

<p><img src="/assets/images/Post_Images/Figure3.jpg" alt="Figure 3" /></p>

<p><img src="/assets/images/Post_Images/Figure4.jpg" alt="Figure 4" /></p>

<h2 id="conclusions">Conclusions:</h2>

<ul>
  <li>
    <p>The pairwise analysis of AKI and non-AKI patients showed that AKI patients varied significantly in many traits including vitals, laboratory results, and commorbidities</p>
  </li>
  <li>
    <p>Pairwise comparisons of outcomes showed significantly higher time in the ICU and time on mechanical ventilation for patients who were AKI classified.</p>
  </li>
  <li>
    <p>LASSO logistic regression identified the increased risk of developing AKI for patients with higher BMI, with hypo-osmolality/hypo-natremia, and on certain classes of medications, especially diuretics, anti-infectives, and gastrointestinal agents.</p>
  </li>
  <li>
    <p>The non-proportional hazards model predicting mortality showed that severe AKI patients have a mortality risk that dramatically rises over time, as compared to stage 1 and stage 2 patients who have static mortality risk. This highlights the severe danger of entering stage 3 AKI without recovering.</p>
  </li>
  <li>
    <p>The non-proportional hazards model predicting recovery showed that stage 1 AKI patients have a recovery risk that dramatically rises over time, as compared to more severe stages. This suggests that patients who develop AKI and can be kept to a low stage are likely to recover quickly. This emphasizes the importance of mitigation and reducing the potential for further kidney damage (such as by stressful medication regimes) that could worsen AKI condition and thus the potential for adverse outcomes.</p>
  </li>
</ul>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Making A Github Hosted Website With Jekyll And Ruby</title><link href="https://jacobstrock.com/2022/02/05/Making-a-Github-Hosted-Website-with-Jekyll-and-Ruby.html" rel="alternate" type="text/html" title="Making A Github Hosted Website With Jekyll And Ruby" /><published>2022-02-05T00:00:00+00:00</published><updated>2022-02-05T00:00:00+00:00</updated><id>https://jacobstrock.com/2022/02/05/Making-a-Github-Hosted-Website-with-Jekyll-and-Ruby</id><content type="html" xml:base="https://jacobstrock.com/2022/02/05/Making-a-Github-Hosted-Website-with-Jekyll-and-Ruby.html"><![CDATA[<p><img src="/assets/images/jekyll_icon.png" alt="jekyll icon" /></p>

<p>Having just completed this website, I thought it would be befitting to first post what I learned about building a static website, and how it can help you in your professional journey. A personal website can be a great tool to teach others, build your network, and hey-show off some of your hard work. These are all reasons why I built this site. If you’re also in industry like me, probably most of what you do is confidential, but it can still be a good place to share techniques and open source examples.</p>

<p>This post will be about how to setup a free website of your own using Github pages, how to customize it as much as your heart desires with Jekyll and Ruby, and last how to add some extra flair.</p>

<h2 id="background">Background</h2>

<p><strong>What is Github Pages?</strong></p>

<p>Github Pages are public web pages any user can utilize that will be freely hosted on Github. Given this is Github based, you’ll need a Github account. It would also be helpful to have git on your desktop.</p>

<p><strong>What is Jekyll?</strong></p>

<p>Jekyll is an open source static site generator with which you can easily write content like this in basic Markdown, use HTML and CSS for structure and presentation. Jekyll does all the hard work of compiling this into HTML so you don’t have to. If you’ve ever had to write in HTML you’ll quickly learn to appreciate Jekyll.</p>

<p><strong>What is Ruby?</strong></p>

<p>Ruby is the programming language Jekyll is written in. If you’re doing anything ordinary you probably won’t need to write anything in Ruby, but it is helpful to know that Ruby underlies Jekyll for building the site.</p>

<h2 id="building-your-site">Building Your Site</h2>

<p>It is possible to build your site either with Jekyll or without. We will overview both options here:</p>

<p><strong>Option 1</strong>:
If you want the easiest route that gives pretty good results, you can do everything from Github without really having to think about Jekyll. To do this, the following will get you setup:</p>
<ol>
  <li>Add a repository with the name <em>username.github.io</em></li>
  <li>Under the repository, go to “Settings”</li>
  <li>Under “Code &amp; operations” go to pages</li>
  <li>Choose a theme from the default templates</li>
  <li>Add content to the README.md as desired</li>
  <li>You can change the title and description with “title:<em>yourtitle</em>” and “description:<em>yourdescription</em>” by adding these to the _config.yml file</li>
</ol>

<p><em>Voila</em>, you have made a site under the url <em>https://username.github.io</em> . If you want to make additions, such as to add more pages, you can do so with Jekyll. If you are taking this option 1 route, you can see the github documentation <a href="https://docs.github.com/en/pages/quickstart">here</a> for additional details. Do note however, that it may take a few minutes for changes to update.</p>

<p><strong>Option 2</strong>:</p>

<p>This second option is for those who want more control. With this, I will cover how to use custom themes, adapt them to your needs, add pages, add posts, and even getting a custom domain name for your website.</p>

<h3 id="using-a-custom-theme-and-template">Using a custom theme and template</h3>
<p>The amount of open source themes for Jekyll is astounding. With little effort, you can make use themes built with the design skill of professional web designers. While there are a wealth of themes of high quality, it can be a little intimidating at first to know how to update and implement them for your own needs, especially if like me you were not familiar with Jekyll and web-design before hand. Do not worry, I will take you through how to build a beautiful site with the example of the <em>minimal mistakes</em> theme. If you are interested in another theme, you can find a gallery of downloadable, github page compatible themes <a href="https://jekyllthemes.io/github-pages-themes">here</a>.</p>

<p>There are actually several ways to implement the minimal mistakes theme, but I recommend forking the repository and using this as a template. Obviously, with your own forked version of the template, it let’s us make more changes down the line since we have access to all the code.</p>

<p>To build your Github page from the repository via forking, simply navigate to the minimal mistakes <a href="https://github.com/mmistakes/minimal-mistakes">repository</a>. Click the fork icon on the top right menu like such:</p>

<p><img src="\assets\images\Post_Images\Fork_screenshot.PNG" alt="fork icon" /></p>

<p>As in option 1, we need to rename this repository on our own profile with name <em>username.github.io</em>. Under the forked repository, you can do this simply by clicking on settings on the menu bar, and typing the new name of your repository in the top box:</p>

<p><img src="\assets\images\Post_Images\Rename_screenshot.PNG" alt="repository rename" /></p>

<p>Under “Code &amp; operations” go to pages. Your github site should now be up and running on <em>https://username.github.io</em>.</p>

<p>Of course, what you see are all the default pages and content for this theme. How do we include our information and customize?</p>

<h3 id="building-and-serving-locally">Building and Serving Locally</h3>

<p>Because we are really starting with a blank template of a site, and you are going to want to visualize your changes as you go, it is best to add your content locally. In essence, adding everything is possible directly from your profile it Github but it will be particularly painful because commits will take several minutes to take effect.</p>

<p>For your local environment, you will need git installed and ssh-key properly setup. You will also need Jekyll and Ruby. For installation and setup, I will point you to an excellent tutorial for both <a href="https://www.youtube.com/watch?v=LfP7Y9Ja6Qc&amp;list=PLLAZ4kZ9dFpOPV5C5Ay0pHaa0RJFhcmcB&amp;index=3">Windows</a> and <a href="https://www.youtube.com/watch?v=WhrU9m82Wm8&amp;list=PLLAZ4kZ9dFpOPV5C5Ay0pHaa0RJFhcmcB&amp;index=2">Mac</a>. Last, you will need a text editor, I recommend Visual Studio Code, because it facilitates fast staging, commits, and push to your Github. This means you’ll be able to develop quickly and easily. Lets get started.</p>

<p>First, clone your Github repo locally. You can do this from Git Bash via _git clone <your repo="" url="">_. You now have all the template files locally on your computer where you can edit them.</your></p>

<p>From your command line, navigate to your cloned repo and enter <em>bundle exec jekyll serve</em>. This will serve the site locally on your PC. It should default to localhost:4000, which you can type in any browser. Changes to posts and pages will take place immediately, but config changes will require quitting and restarting the serve command. Nevertheless, this will let you start making additions and changes to your site while seeing how they impact the webpage.</p>

<p>With your PC serving your site locally, go ahead and navigate to your repository folder in VS code. There are several major folders and files to adapt the site to your needs:</p>

<ol>
  <li>_ <em>config.yml</em> : Includes most of the site-wide configuration, and home page attributes. If you are working from a template, this should be pretty straight forward to adapt to your use. Just replace</li>
  <li>_ <em>posts</em>: Includes markdown files each with an individual post</li>
  <li>_ <em>pages</em>: Includes markdown files for separate pages on the site</li>
  <li>_ <em>data</em>: Includes important reference data across the site such as dictionary of page names and associated URL</li>
  <li>_ <em>assets</em>: A place you can put documents and images to link and embed in your text</li>
</ol>

<h3 id="custom-domain-name">Custom domain name</h3>

<p>So far so good. But if you’re like me you might be bothered by having to stick with the standard domain name for your site. If you want to get creative or maybe just don’t want to have <em>.github.io</em> in the address, not to fear, Github has made this easy.</p>

<p>If you don’t already own a domain name, this is pretty simple. There are a number of domain name services. I chose GoDaddy.com, but it doesn’t matter which you use.</p>

<p>Once you buy a domain name, you’ll have to make a few changes with your domain managment and Github to get it working, but it’s a sinch.</p>

<p>On the DNS management page, you need to make the following changes:</p>
<ol>
  <li>For variable “A”, update the IP address to: 185.199.108.153 to point your domain to Github’s server over HTTPS</li>
  <li>Add three for variable “A” with the following IP addresses: 185.199.109.153, 185.199.110.153, 185.199.111.153</li>
  <li>In CNAME input your current Github pages site <em>username.github.io</em></li>
</ol>

<p>In the Github repository for your site, add a file “CNAME” in the root directory. In CNAME, add your purchased domain name.</p>]]></content><author><name>Jacob P. Strock</name></author><summary type="html"><![CDATA[]]></summary></entry></feed>